

จากการสร้าง Convolutional Neural Network ไปจนถึงการ Deploy OCR บน iOS
แรงจูงใจของโปรเจกต์ ✍️ ??
ขณะเรียนสร้าง Deep Learning Models สำหรับข้อมูล MNIST หลายเดือนก่อน ผมสร้างแอป iOS ที่จดจำตัวอักษรลายมือได้
เพื่อน Kaichi Momose กำลังพัฒนาแอปเรียนภาษาญี่ปุ่น Nukon ต้องการฟีเจอร์คล้ายกัน จึงร่วมมือสร้าง OCR (Optical Character Recognition) สำหรับตัวอักษรญี่ปุ่น (Hiragana และ Katakana) ที่ซับซ้อนกว่าการจดจำตัวเลข
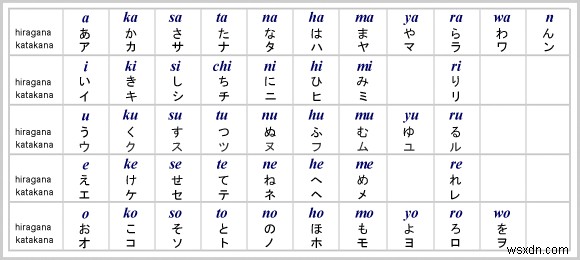
ระหว่างพัฒนา Nukon ไม่มี API สำหรับจดจำลายมือภาษาญี่ปุ่น จึงต้องสร้าง OCR เอง ประโยชน์มากที่สุดคือทำงาน Offline ได้ ผู้ใช้อยู่ในป่าลึกโดยไม่มีอินเทอร์เน็ตก็เปิด Nukon เรียนรู้ภาษาญี่ปุ่นประจำวันได้ เราเรียนรู้มาก และสำคัญคือปลุกให้ตื่นเต้นที่ส่งมอบ Product ที่ดีกว่าให้ผู้ใช้
บทความนี้แยกขั้นตอนการสร้าง Japanese OCR สำหรับ iOS Apps สำหรับผู้อยากสร้างสำหรับภาษา/สัญลักษณ์อื่น สามารถปรับแต่งได้โดยเปลี่ยน Dataset
โดยไม่พูดนาน มาดูสิ่งที่จะครอบคลุม:
Part 1️⃣: ได้ Dataset และ Preprocess Images
Part 2️⃣: สร้างและ Train CNN (Convolutional Neural Network)
Part 3️⃣: ผสาน Model ที่ Train แล้วเข้ากับ iOS
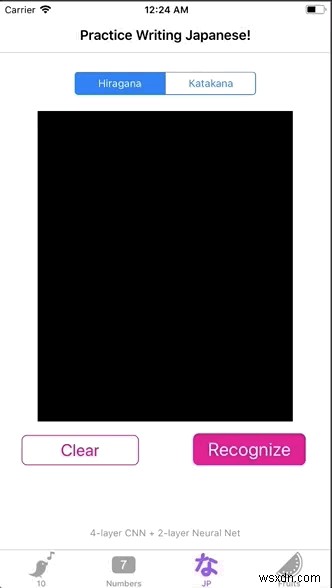
ได้ Dataset และ Preprocess Images ?
Dataset มาจาก ETL Character Database ที่มี 9 ชุดรูปภาพตัวอักษรและสัญลักษณ์ลายมือ เนื่องจากจะสร้าง OCR สำหรับ Hiragana จึงใช้ Dataset ETL8
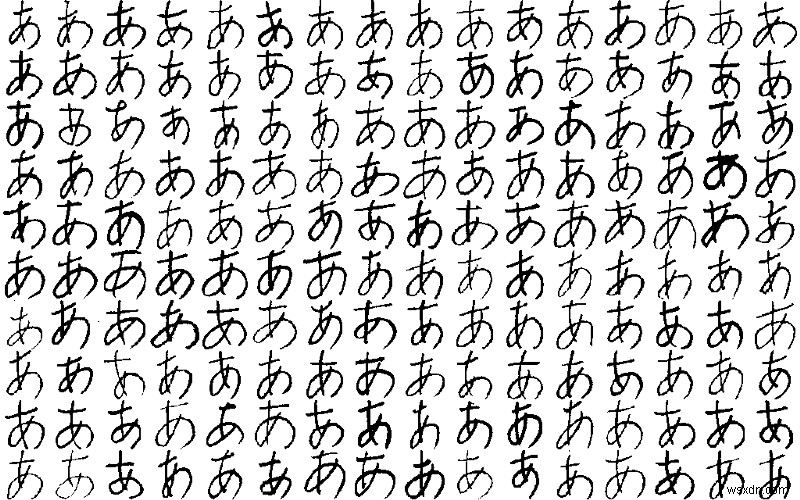
เพื่อดึงรูปภาพจาก Database ต้องใช้ Helper Functions อ่านและเก็บรูปในรูปแบบ .npz
import struct import numpy as np from PIL import Image sz_record = 8199 def read_record_ETL8G(f): s = f.read(sz_record) r = struct.unpack('>2H8sI4B4H2B30x8128s11x', s) iF = Image.frombytes('F', (128, 127), r[14], 'bit', 4) iL = iF.convert('L') return r + (iL,) def read_hiragana(): # Type of characters = 70, person = 160, y = 127, x = 128 ary = np.zeros([71, 160, 127, 128], dtype=np.uint8) for j in range(1, 33): filename = '../../ETL8G/ETL8G_{:02d}'.format(j) with open(filename, 'rb') as f: for id_dataset in range(5): moji = 0 for i in range(956): r = read_record_ETL8G(f) if b'.HIRA' in r[2] or b'.WO.' in r[2]: if not b'KAI' in r[2] and not b'HEI' in r[2]: ary[moji, (j - 1) * 5 + id_dataset] = np.array(r[-1]) moji += 1 np.savez_compressed("hiragana.npz", ary)ได้ hiragana.npz แล้ว เริ่ม Process รูปภาพโดยโหลดไฟล์และ ปรับขนาดรูปเป็น 32x32 pixels เพิ่ม Data Augmentation สร้างรูปเพิ่มที่หมุนและซูม เมื่อ Model Train ด้วยรูปตัวอักษรจากมุมต่างๆ จะปรับตัวเข้ากับลายมือคนได้ดีขึ้น
import scipy.misc from keras.layers import Conv2D, MaxPooling2D from keras.layers import Dense, Dropout, Activation, Flatten from keras.models import Sequential from keras.preprocessing.image import ImageDataGenerator from keras.utils import np_utils from sklearn.model_selection import train_test_split # 71 characters nb_classes = 71 # input image dimensions img_rows, img_cols = 32, 32 ary = np.load("hiragana.npz")['arr_0'].reshape([-1, 127, 128]).astype(np.float32) / 15 X_train = np.zeros([nb_classes * 160, img_rows, img_cols], dtype=np.float32) for i in range(nb_classes * 160): X_train[i] = scipy.misc.imresize(ary[i], (img_rows, img_cols), mode='F') y_train = np.repeat(np.arange(nb_classes), 160) X_train, X_test, y_train, y_test = train_test_split(X_train, y_train, test_size=0.2) # convert class vectors to categorical matrices y_train = np_utils.to_categorical(y_train, nb_classes) y_test = np_utils.to_categorical(y_test, nb_classes) # data augmentation datagen = ImageDataGenerator(rotation_range=15, zoom_range=0.20) datagen.fit(X_train)สร้างและ Train CNN ?️
ถึงส่วนสนุก! ใช้ Keras สร้าง CNN (Convolutional Neural Network) สำหรับ Model ตอนแรกทดลอง Hyper-parameters และปรับหลายครั้ง Combination ด้านล่างให้ Accuracy สูงสุด — 98.77% ลองปรับ Parameter เองได้
model = Sequential() def model_6_layers(): model.add(Conv2D(32, 3, 3, input_shape=input_shape)) model.add(Activation('relu')) model.add(Conv2D(32, 3, 3)) model.add(Activation('relu')) model.add(MaxPooling2D(pool_size=(2, 2))) model.add(Dropout(0.5)) model.add(Conv2D(64, 3, 3)) model.add(Activation('relu')) model.add(Conv2D(64, 3, 3)) model.add(Activation('relu')) model.add(MaxPooling2D(pool_size=(2, 2))) model.add(Dropout(0.5)) model.add(Flatten()) model.add(Dense(256)) model.add(Activation('relu')) model.add(Dropout(0.5)) model.add(Dense(nb_classes)) model.add(Activation('softmax')) model_6_layers() model.compile(loss='categorical_crossentropy', optimizer='adam', metrics=['accuracy']) model.fit_generator(datagen.flow(X_train, y_train, batch_size=16), samples_per_epoch=X_train.shape[0], nb_epoch=30, validation_data=(X_test, y_test))เคล็ดลับหาก Performance ของ Model ไม่เป็นที่พอใจ ในขั้นตอน Train:
Model Overfitting
หมายถึง Model ไม่ Generalize ดี ดูบทความนี้สำหรับคำอธิบายที่เข้าใจง่าย
วิธีตรวจจับ Overfitting: acc (Accuracy) เพิ่มขึ้นเรื่อยๆ แต่ val_acc (Validation Accuracy) ทำตรงข้ามระหว่าง Train
วิธีแก้ Overfitting: Regularization (เช่น Dropouts), Data Augmentation, ปรับปรุงคุณภาพ Dataset
วิธีรู้ว่า Model "กำลังเรียนรู้"
Model ไม่เรียนรู้หาก val_loss (Validation Loss) เพิ่มขึ้นหรือไม่ลดลงขณะ Train
ใช้ TensorBoard — ให้ Visualization ประสิทธิภาพ Model ตามเวลา กระจายงานดู Epoch ทีละอันและเปรียบเทียบค่าตลอดเวลา
เมื่อพอใจ Accuracy แล้ว ลบ Dropout Layers ก่อน Save Weights และ Model Config เป็นไฟล์
for k in model.layers: if type(k) is keras.layers.Dropout: model.layers.remove(k) model.save('hiraganaModel.h5')งานสุดท้ายก่อนเข้าส่วน iOS คือแปลง hiraganaModel.h5 เป็น CoreML Model
import coremltools output_labels = [ 'あ', 'い', 'う', 'え', 'お', 'か', 'く', 'こ', 'し', 'せ', 'た', 'つ', 'と', 'に', 'ね', 'は', 'ふ', 'ほ', 'み', 'め', 'や', 'ゆ', 'よ', 'ら', 'り', 'る', 'わ', 'が', 'げ', 'じ', 'ぞ', 'だ', 'ぢ', 'づ', 'で', 'ど', 'ば', 'び', 'ぶ', 'べ', 'ぼ', 'ぱ', 'ぴ', 'ぷ', 'ぺ', 'ぽ', 'き', 'け', 'さ', 'す', 'そ', 'ち', 'て', 'な', 'ぬ', 'の', 'ひ', 'へ', 'ま', 'む', 'も', 'れ', 'を', 'ぎ', 'ご', 'ず', 'ぜ', 'ん', 'ぐ', 'ざ', 'ろ'] scale = 1/255. coreml_model = coremltools.converters.keras.convert('./hiraganaModel.h5', input_names='image', image_input_names='image', output_names='output', class_labels= output_labels, image_scale=scale) coreml_model.author = 'Your Name' coreml_model.license = 'MIT' coreml_model.short_description = 'Detect hiragana character from handwriting' coreml_model.input_description['image'] = 'Grayscale image containing a handwritten character' coreml_model.output_description['output'] = 'Output a character in hiragana' coreml_model.save('hiraganaModel.mlmodel')output_labels คือ Output ทั้งหมดที่จะเห็นใน iOS ต่อไป
ความน่าสนใจ: ถ้าเข้าใจญี่ปุ่น อาจรู้ว่าลำดับตัวอักษร Output ไม่ตรง "ลำดับอักษร" ของ Hiragana ใช้เวลาพอคุ้มค่ารู้ว่า ETL8 ไม่อยู่ใน "ลำดับอักษร" (ขอบคุณ Kaichi ที่ค้นพบ) Dataset คอมไพล์โดยมหาวิทยาลัยญี่ปุ่น แต่…?
ผสาน Model ที่ Train แล้วเข้า iOS ?
สุดท้ายรวมทุกอย่าง! Drag และ Drop hiraganaModel.mlmodel เข้า Xcode Project จะเห็นแบบนี้:
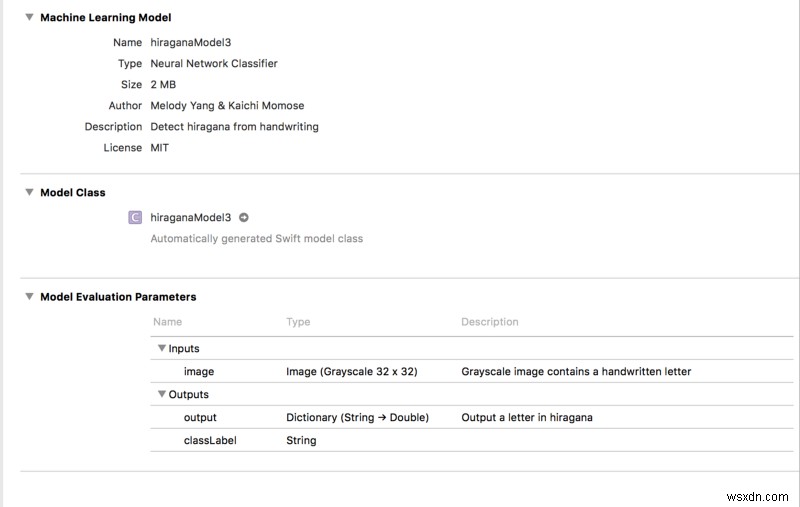
หมายเหตุ: Xcode สร้าง Workspace เมื่อ Copy Model ต้อง Switch Coding Environment ไปที่ Workspace ไม่งั้น ML Model จะไม่ทำงาน!
เป้าหมายคือให้ Hiragana Model ทายตัวอักษรโดยส่งรูปภาพเข้าไป ทำได้โดยสร้าง UI ให้ผู้ใช้เขียน เก็บการเขียนเป็นรูปภาพ ดึงค่า Pixel ของรูปส่งให้ Model
มาทำทีละขั้นตอน:
- “วาด” ตัวอักษรบน
UIViewด้วยUIBezierPath
import UIKit class viewController: UIViewController { @IBOutlet weak var canvas: UIView! var path = UIBezierPath() var startPoint = CGPoint() var touchPoint = CGPoint() override func viewDidLoad() { super.viewDidLoad() canvas.clipsToBounds = true canvas.isMultipleTouchEnabled = true } override func touchesBegan(_ touches: Set<UITouch>, with event: UIEvent?) { let touch = touches.first if let point = touch?.location(in: canvas) { startPoint = point } } override func touchesMoved(_ touches: Set<UITouch>, with event: UIEvent?) { let touch = touches.first if let point = touch?.location(in: canvas) { touchPoint = point } path.move(to: startPoint) path.addLine(to: touchPoint) startPoint = touchPoint draw() } func draw() { let strokeLayer = CAShapeLayer() strokeLayer.fillColor = nil strokeLayer.lineWidth = 8 strokeLayer.strokeColor = UIColor.orange.cgColor strokeLayer.path = path.cgPath canvas.layer.addSublayer(strokeLayer) } // ล้างการวาดใน View @IBAction func clearPressed(_ sender: UIButton) { path.removeAllPoints() canvas.layer.sublayers = nil canvas.setNeedsDisplay() } }strokeLayer.strokeColor เป็นสีไหนก็ได้ แต่สีพื้นหลังของ canvas ต้องเป็น ดำ แม้รูป Train จะมีพื้นหลังขาวและขีดสีดำ Model ไม่ตอบสนองดีกับ Input Image สไตล์นั้น
2. แปลง UIView เป็น UIImage และดึงค่า Pixel ด้วย CVPixelBuffer
ใน Extension มี Helper Functions 2 ตัว ร่วมกันแปลงรูปเป็น Pixel Buffer เทียบเท่าค่า Pixel Input width และ height ต้องเป็น 32 ทั้งคู่ เนื่องจาก Input Dimensions ของ Model คือ 32x32 Pixels
เมื่อได้ pixelBuffer เรียก model.prediction() ส่ง pixelBuffer เข้าไป ได้ Output classLabel แล้ว!
@IBAction func recognizePressed(_ sender: UIButton) { // แปลง View เป็น Image let resultImage = UIImage.init(view: canvas) let pixelBuffer = resultImage.pixelBufferGray(width: 32, height: 32) let model = hiraganaModel3() // ทายตัวอักษร Hiragana let output = try? model.prediction(image: pixelBuffer!) print(output?.classLabel) } extension UIImage { // Resize รูปเป็น width x height และแปลงเป็น Grayscale CVPixelBuffer func pixelBufferGray(width: Int, height: Int) -> CVPixelBuffer? { return _pixelBuffer(width: width, height: height, pixelFormatType: kCVPixelFormatType_OneComponent8, colorSpace: CGColorSpaceCreateDeviceGray(), alphaInfo: .none) } func _pixelBuffer(width: Int, height: Int, pixelFormatType: OSType, colorSpace: CGColorSpace, alphaInfo: CGImageAlphaInfo) -> CVPixelBuffer? { var maybePixelBuffer: CVPixelBuffer? let attrs = [kCVPixelBufferCGImageCompatibilityKey: kCFBooleanTrue, kCVPixelBufferCGBitmapContextCompatibilityKey: kCFBooleanTrue] let status = CVPixelBufferCreate(kCFAllocatorDefault, width, height, pixelFormatType, attrs as CFDictionary, &maybePixelBuffer) guard status == kCVReturnSuccess, let pixelBuffer = maybePixelBuffer else { return nil } CVPixelBufferLockBaseAddress(pixelBuffer, CVPixelBufferLockFlags(rawValue: 0)) let pixelData = CVPixelBufferGetBaseAddress(pixelBuffer) guard let context = CGContext(data: pixelData, width: width, height: height, bitsPerComponent: 8, bytesPerRow: CVPixelBufferGetBytesPerRow(pixelBuffer), space: colorSpace, bitmapInfo: alphaInfo.rawValue) else { return nil } UIGraphicsPushContext(context) context.translateBy(x: 0, y: CGFloat(height)) context.scaleBy(x: 1, y: -1) self.draw(in: CGRect(x: 0, y: 0, width: width, height: height)) UIGraphicsPopContext() CVPixelBufferUnlockBaseAddress(pixelBuffer, CVPixelBufferLockFlags(rawValue: 0)) return pixelBuffer } } 3. แสดงผลด้วย UIAlertController
ขั้นตอนนี้ Optional ตาม GIF ตอนต้น ผมเพิ่ม Alert Controller แจ้งผลลัพธ์
func informResultPopUp(message: String) { let alertController = UIAlertController(title: message, message: nil, preferredStyle: .alert) let ok = UIAlertAction(title: "Ok", style: .default, handler: { action in self.dismiss(animated: true, completion: nil) }) alertController.addAction(ok) self.present(alertController, animated: true) { () in } }Voila! เราสร้าง OCR พร้อม Demo (และพร้อม App Store) แล้ว! ??
สรุป ?
การสร้าง OCR ไม่ยากมาก ตามที่เห็น บทความนี้ประกอบด้วยขั้นตอนและปัญหาที่เจอขณะสร้างโปรเจกต์ ผมเพลิดเพลินกับการทำให้ Python Code กลายเป็น Demo ได้จริงผ่าน iOS และตั้งใจทำต่อ
หวังว่าบทความนี้ให้ข้อมูลประโยชน์แก่ผู้อยากสร้าง OCR แต่ไม่รู้เริ่มที่ไหน
หา Source Code ได้ที่นี่.
Bonus: สนใจลอง Shallow Algorithms อ่านต่อได้เลย!
[Optional] Train With Shallow Algorithms ?
ก่อน Implement CNN เราและ Kaichi ทดสอบ ML Algorithms อื่นๆ ว่าทำได้ไหม (และประหยัด Computing Cost!) เลือก KNN และ Random Forest
ประเมิน Performance ด้วย Baseline Accuracy = 1/71 = 0.014
สมมติคนไม่รู้ภาษาญี่ปุ่น โอกาสทายตัวอักษรถูก 1.4% Model ถือว่าทำได้ดีถ้า Accuracy เกิน 1.4% ดูว่าจริงไหม ?
KNN
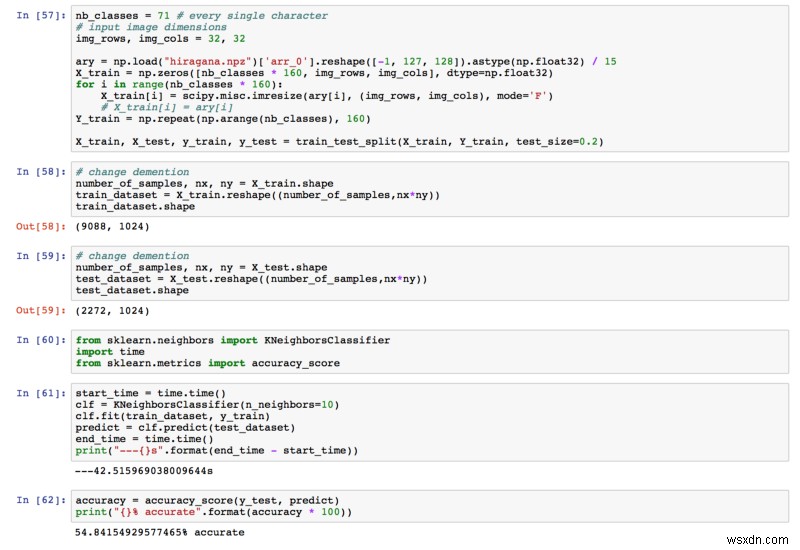
Accuracy สุดท้าย 54.84% สูงกว่า 1.4% มากแล้ว!
Random Forest
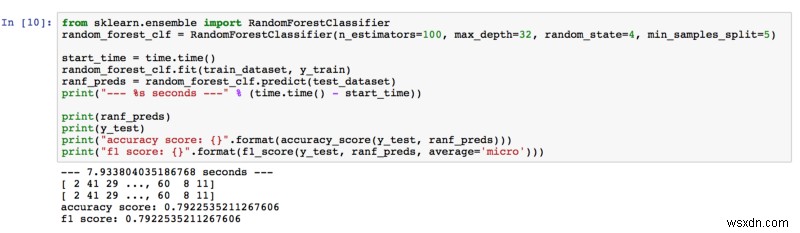
Accuracy 79.23% Random Forest เกินความคาดหมาย ขณะ Tune Hyper-parameters ได้ผลดีขึ้นโดยเพิ่ม Estimators และ Tree Depth คิดว่า Trees มากขึ้น = เรียนรู้ Features ในรูปมากขึ้น Tree ลึกขึ้น = เรียนรายละเอียดจาก Features มากขึ้น
สนใจเรียนเพิ่ม เจอ Paper นี้เกี่ยวกับ Image Classification ด้วย Random Forest
ขอบคุณที่อ่าน ความคิดเห็นและ Feedback ยินดีต้อนรับ!
