

เผยแพร่เมื่อวันที่ 19 เมษายน 2569 เวลา 10:00 น. EDT
Afam มีประสบการณ์ tech publishing ตั้งแต่ 2018 ทำงานที่ Make Tech Easier ตลอดปีสร้าง reputation สำหรับ high-quality guides, reviews, tips, และ explainer articles ครอบคลุม Windows, Linux, และ open source tools งาน featured บน top websites รวม Technical Ustad, Windows Report, Guiding Tech, Alphr, และ Next of Windows
มีปริญญาตรี Computer Science และเป็น strong advocate สำหรับ data privacy และ security มี tips, videos, tutorials บน Fuzo Tech YouTube channel
ตอนไม่ได้งาน ชอบใช้เวลากับครอบครัว ปั่นจักรยาน หรือดูแลสวน
ผมชอบใช้ Linux เพราะ stability แต่ home server ที่รัน 24/7 ดูเหมือน push มันถึงขีดจำกัด และเห็นมัน hang ที่ worst possible moments บางครั้งต้อง manual reboot เพื่อให้ remote box กลับมาออนไลน์
ถ้านี่คือ scenario ที่คุณเจอ Linux มี built-in system ที่ perfect สำหรับ situations เหล่านี้ Combine กับ systemd's service recovery ให้ efficient two-layer crash recovery mechanism ที่ไม่ต้อง physical intervention
 บทความเกี่ยวข้อง
Linux มี built-in recovery mechanism อยู่แล้ว
Watchdog timer ที่ปกป้องระบบของคุณ
Linux มี built-in feature ชื่อ watchdog ทำงานหลักการที่ระบบส่งสัญญาณเป็นประจำแสดงว่ายัง active ระหว่างที่ไม่ได้รับ signal จากระบบ watchdog assume มีปัญหาและ trigger reboot Feature นี้ exist ตั้งแต่ mid-1990s บน Linux และใช้หลักกับ systems ที่ uptime non-negotiable อย่าง servers และ embedded systems
บนบางระบบ watchdog exposed ผ่าน /dev/watchdog device file ในขณะที่อื่นอาจเป็น /dev/watchdog0 Process ต้อง write ไปที่ file นี้เพื่อ reset countdown timer ถ้า process หยุด write มักหมายถึงระบบ frozen หรือ resources ถูก consumed by runaway process ในกรณีนี้ timer expires และนั่นคือวิธีที่ reboot ถูก trigger
มีสองประเภท watchdogs: hardware และ software (softdog) ตัวแรกอาจเป็น hardware mechanism บน motherboard มัน always capable of system resets แม้ตอน kernel completely locked up ตัวถัดไปคือ software version ที่รันใน kernel และไม่ต้อง extra hardware เวอร์ชันนี้ however ไม่ save คุณถ้ามี kernel crash
Type
Needs dedicated hardware
Survives a hard kernel crash
Best suited for
Hardware watchdog
Yes
Yes
Servers, always-on critical systems
Software (softdog)
No
No
Home servers, VMs, general-purpose rigs
Software watchdog great สำหรับ common freezes ที่ setups ส่วนใหญ่เจอ เช่น load spikes, memory exhaustion, และ runaway processes แต่ feature นี้ disabled by default และ misconfiguring มันอาจ cause unnecessary และ repeated system reboots นั้น said มันกลายเป็น one of my favorite hidden Linux features
ตั้งค่า automatic crash recovery ในไม่กี่นาที
Practical watchdog setup ที่ทำงานจริง
softdog already works บน almost all Linux distros ดังนั้นไม่ต้อง hardware ใหม่ Starting point คือ load module ด้วยคำสั่ง:
sudo modprobe softdog
เพื่อให้ softdog persists หลัง reboots เปิด file ที่ /etc/modules (Debian/Ubuntu) เพิ่ม softdog บรรทัดของตัวเอง และ save ตอนนี้ install watchdog daemon และ enable ด้วยคำสั่ง:
sudo apt install watchdog
sudo systemctl enable --now watchdog
ทำแล้วเปิด /etc/watchdog.conf และ focus important settings:
Setting
What it controls
Practical starting point
interval
บ่อยแค่ไหนที่ระบบ check in
10 seconds
max-load-1
Load average ceiling ก่อน reboot
~6× CPU core count
min-memory
Free memory floor ก่อน reboot
~512 pages (~2MB)
Load average สำหรับ max-load-1 คือหนึ่งนาที ค่านี้ represent จำนวน processes ที่ actively compete for CPU time บน device นี้ imply ว่าถ้า 4-core machine มี load 4.0 ทุก core fully occupied safer ที่จะใช้ 6x core count เพื่อให้ระบบมี headroom สำหรับ bursts ที่อาจ legitimate ก่อน lockup
Note ว่า min-memory specified ใน memory pages ไม่ใช่ megabytes หนึ่ง page typically 4KiB บน x86_64 systems ตามนี้ 512 pages ประมาณ 2MB free memory
ครบ configurations รันคำสั่ง systemctl status watchdog verify daemon running และ journalctl -u watchdog review activity
Stopping watchdog service won't trigger reboot — daemon closes /dev/watchdog cleanly on exit ซึ่ง safely disarms timer ถ้าอยาก test จริงว่า watchdog จะ reboot system คุณต้อง simulate real failure condition เช่น sustained load spike
ไม่ใช่ทุก crash ที่ต้อง reboot
ให้ systemd แก้ broken services ในไม่กี่วินาที
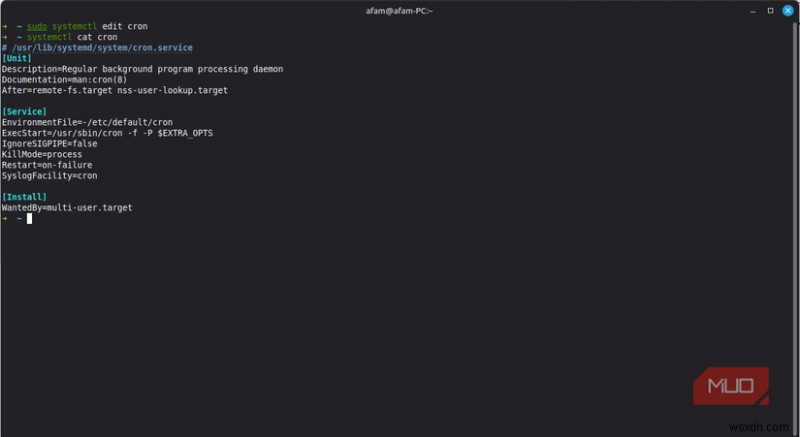
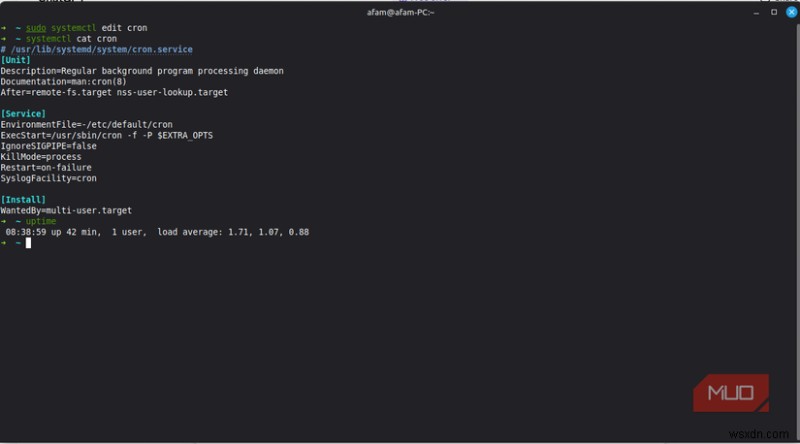
มี failures หลายอย่างที่ systemd handle ในวินาทีโดยไม่ต้อง reboot system ตัวอย่างคือ service ที่ crashes, exits unexpectedly, หรือ stops responding คุณ apply checks ให้ไม่ทุกอย่าง trigger reboot โดยไม่สัมผัส original unit รันคำสั่งด้านล่างเพิ่ม service name:
sudo systemctl edit
จากนั้นเพิ่ม:
[Service]
Restart=on-failure
RestartSec=5
Restart=on-failure ensure restart happens only เมื่อ service exits with error code และ RestartSec=5 คือ short delay ก่อน actual restarts ป้องกัน rapid-fire restart loop
Combine StartLimitIntervalSec และ StartLimitBurst จะ prevent broken service จาก restarting indefinitely พวกมัน essential ในการหยุด crash loop แตทำงานได้แค่ services ที่รันใน systemd
Two layers of recovery ที่ cover เกือบทุก failure
Neither watchdog หรือ systemd Service Management complete alone แต่ใช้ร่วมกัน handle almost anything
Failure type
Recovery layer
Expected outcome
Service exits with an error
systemd (Restart=on-failure)
Service restarts within seconds
Service exits cleanly but shouldn't
systemd (Restart=always)
Service restarts within seconds
Full system freeze or load spiral
watchdog daemon
Automatic reboot, no manual step
systemd well-suited catching และ restarting individual service failures และ watchdog นั่งเหนือมันดู whole system และ trigger restart เมื่อสิ่งผิดพลาดไป beyond limits ของ systemd
Combination นี้หมายถึงคุณไม่ต้อง available ทุกครั้งที่สิ่งผิดพลาด และทำให้ server management pleasant มากกว่า ยัง consider เรียนรู้ specific Linux commands ที่ช่วย fix ส่วนใหญ่ของ system problems
