

หลาย Choices ที่เราทำ Revolve Around Numerical Relationships (ความสัมพันธ์เชิงตัวเลข)
- เรากิน Foods บางอย่างเพราะ Science บอก Lower Cholesterol
- เรา Further Education เพราะ Likely Increased Salary
- เราซื้อบ้านใน Neighborhood ที่เชื่อว่า Appreciate ใน Value มากที่สุด
เรามาถึง Conclusions นี้ยังไง? Most Likely Someone Gathered Large Amount of Data และ Used It To Form Conclusions One Common Technique คือ Linear Regression Form ของ Supervised Learning สำหรับ Info เพิ่มเติม Supervised Learning และ Examples ใช้ไหน ไป Part 1 ของซีรีส์
Linear Relationships
เมื่อสอง Values — เรียก x และ y — มี Linear Relationship หมายถึง Change x by 1 จะ Cause y Change by Fixed Amount ทางง่ายคือ Examples:
- 10 Pizzas Cost 10x Price ของ One Pizza
- 10-foot-tall Wall Needs Twice Paint ของ 5-foot Wall
Mathematically Relationship นี้ Described Using Equation of a Line:
y = mx + b Math อาจ Dreadfully Confusing แต่บ่อยครั้ง感覺像 Magic ให้ผม ตอนแรกเรียน Equation of a Line ผมจดจำว่าสวยมากที่ Calculate Distance, Slope, และ Other Points บน Line ด้วย Formula เดียว
แต่ How Do You Get This Formula ถ้ามีแค่ Data Points? คำตอบคือ Linear Regression — Very Popular Machine Learning Tool
An Example of Linear Regression
ในโพสต์นี้ เราจะ Explore ว่า Beats Per Minute (BPM) ในเพลง Predict Popularity บน Spotify ได้ไหม
Linear Regression Models Relationship ระหว่าง Two Variables หนึ่งเรียก "Explanatory Variable" อีกหนึ่ง "Dependent Variable"
ในตัวอย่างเรา อยากดู BPM "Explain" Popularity ได้ไหม So BPM = Explanatory Variable ทำให้ Popularity = Dependent Variable
Model จะใช้ Least-squares Regression หา Best Fitting Line Form คุณเดาได้ y = mx + b
While there can be Multiple Explanatory Variables ในตัวอย่างนี้ Simple Linear Regression แค่ One
Least-Squares What?
มี Several Ways ทำ Linear Regression หนึ่งชื่อ "Least-squares" มัน Calculate Best Fitting Line โดย Minimize Sum of Squares ของ Vertical Deviations จากแต่ละ Data Point ไป Line
รู้ว่าสับสน แต่ Basic คือ "Build Me a Line ที่ Minimize Amount of Space ระหว่าง Line และ Data Points"
Reason สำหรับ Squaring และ Summing คือ No Cancellations ระหว่าง Positive และ Negative Values
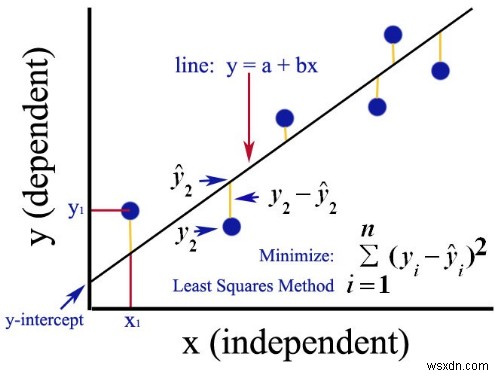
รูปจาก Quora อธิบายดี
The Dataset
เราจะใช้ Dataset จาก Kaggle: https://www.kaggle.com/leonardopena/top50spotify2019 Download as CSV
Dataset มี 16 Columns แต่เรา Care แค่ 3 — "Track Name," "Beats Per Minute," และ "Popularity" One ของ Most Important Steps Machine Learning คือ Getting Data Properly Formatted เรียกว่า "Munging" คุณ Delete All Data Except 3 Columns นี้
CSV ควรเป็น: 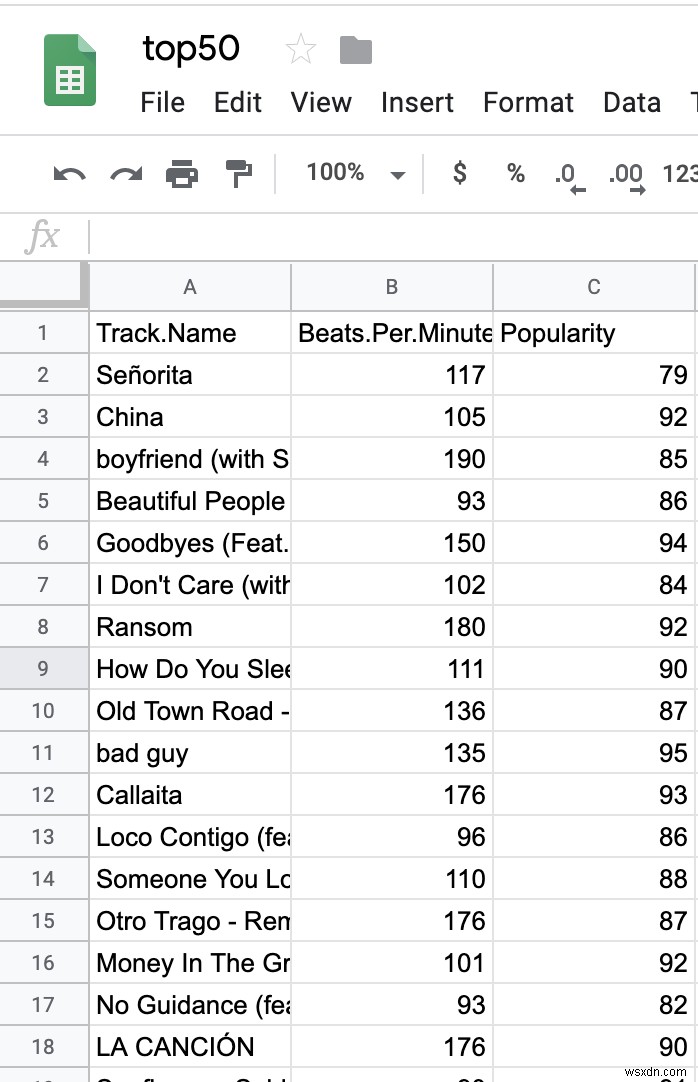
Using Ruby to do the Regression
ในตัวอย่าง ใช้ ruby_linear_regression Gem Install:
gem install ruby_linear_regression OK Ready to Code! สร้าง Ruby File ใหม่ Add Requires:
require "ruby_linear_regression" require "csv" ต่อไป Read CSV Data เรียก #shift Discard Header Row หรือ Delete First Row จาก CSV File
csv = CSV.read("top50.csv") csv.shift สร้าง Two Empty Arrays เก็บ X-data Points และ Y-data Points
x_data = [] y_data = [] ...และ Iterate ด้วย .each เพิ่ม Beats Per Minute Data เข้า X Array และ Popularity Data เข้า Y Array
If Curious See What Happening Experiment Logrowด้วยputsหรือpเช่น:puts row
csv.each do |row| x_data.push( [row[1].to_i] ) y_data.push( row[2].to_i ) end ตอน Use ruby_linear_regression Gem สร้าง New Instance Regression Model Load Data Train Model:
linear_regression = RubyLinearRegression.new linear_regression.load_training_data(x_data, y_data) linear_regression.train_normal_equation ต่อไป Print Mean Square Error (MSE) — Measure ของ Difference ระหว่ Observed Values และ Predicted Values Difference Squared เพื่อ Negative และ Positive ไม่ Cancel Out เรา Minimize MSE เพราะไม่อยาก Distance ระหว่ Predicted และ Actual ใหญ่
puts "Trained model with the following cost fit #{linear_regression.compute_cost}" สุดท้าย ให้ Computer ใช้ Model Predict เฉพาะ: เพลง 250 BPM Popular จะเป็นเท่าไหร่ เล่นได้กับค่าต่างๆ ใน prediction_data Array
prediction_data = [250] predicted_popularity = linear_regression.predict(prediction_data) puts "Predicted popularity: #{predicted_popularity.round}" Results
Run Program ใน Console ดู!
➜ ~ ruby spotify_regression.rb Trained model with the following cost fit 9.504882197447587 Predicted popularity: 91 Cool! เปลี่ยน "250" เป็น "50" ดู Predict
➜ ~ ruby spotify_regression.rb Trained model with the following cost fit 9.504882197447587 Predicted popularity: 86 ปรากฏว่าเพลง BPM มาก กว่า Popular มาก
Entire Program
นี่ Full File ของผม:
require 'csv' require 'ruby_linear_regression' x_data = [] y_data = [] csv = CSV.read("top50.csv") csv.shift # Load data from CSV file into two arrays -- one for independent variables X (x_data) and one for the dependent variable y (y_data) # Row[0] = title # Row[1] = BPM # Row[2] = Popularity csv.each do |row| x_data.push( [row[1].to_i] ) y_data.push( row[2].to_i ) end # Create regression model linear_regression = RubyLinearRegression.new # Load training data linear_regression.load_training_data(x_data, y_data) # Train the model using the normal equation linear_regression.train_normal_equation # Output the cost puts "Trained model with the following cost fit #{linear_regression.compute_cost}" # Predict the popularity of a song with 250 BPM prediction_data = [250] predicted_popularity = linear_regression.predict(prediction_data) puts "Predicted popularity: #{predicted_popularity.round}" Next Steps
นี่ Very Simple Example แต่คุณ Run First Linear Regression แล้ว Key Technique สำหรับ Machine Learning ถ้า Yearn For More นี่ Few Other Things: - Check Source Code Ruby Gem ที่ใช้ ดู Math Under the Hood - กลับ Original Data Set เพิ่ม Additional Variables ลง Model Run Multi-variable Linear Regression ดู Reduce MSE ได้ไหม เช่น "Valence" (Positivity ของเพลง) อาจ Role ใน Popularity - Try Gradient Descent Model ซึ่งรันได้ด้วย ruby_linear_regression Gem
