ใช้ไลบรารี PyPDF2 เพื่อดึงข้อมูลและเมตาดาต้าจาก PDF รวมถึงไฮเปอร์ลิงก์ โดยใช้ Regular Expression ค้นหา URL
ขั้นตอน
- ติดตั้ง:
pip install PyPDF2 - เปิดไฟล์ในโหมด Binary ('rb')
- วนลูปอ่านทุกหน้า ดึงข้อความด้วย extractText()
- ใช้ re.findall() ค้นหา pattern
https?://\S+ - พิมพ์ URL ที่พบ
ตัวอย่างโค้ด
# Import necessary packages
import PyPDF2
import re

# Open The File in Binary mode
file = open("newfile.pdf", 'rb')
readPDF = PyPDF2.PdfFileReader(file)

def find_url(string):
    regex = r"(https?://\S+)"
    url = re.findall(regex, string)
    for u in url:
        return u

# Iterating over all the pages of File
for page_no in range(readPDF.numPages):
    page = readPDF.getPage(page_no)
    text = page.extractText()
    print(find_url(text))

# Close the file
file.close()
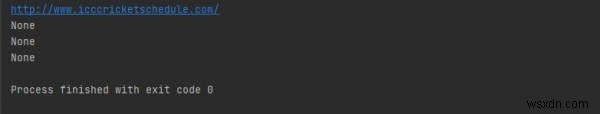
ผลลัพธ์
โค้ดจะพิมพ์ไฮเปอร์ลิงก์ทั้งหมดที่พบใน PDF