

งานของเราคือการ crawl หน้าเว็บและนับความถี่ของคำ แล้วคืนค่าคำที่พบบ่อยที่สุด
เราใช้โมดูล requests และ BeautifulSoup ช่วยสร้าง web crawler ดึงข้อมูลจากหน้าเว็บและเก็บในลิสต์
โค้ดตัวอย่างสมบูรณ์
import requests
from bs4 import BeautifulSoup
import operator
from collections import Counter

def my_start(url):
    my_wordlist = []
    my_source_code = requests.get(url).text
    my_soup = BeautifulSoup(my_source_code, 'html.parser')

    for each_text in my_soup.findAll('div', {'class': 'entry-content'}):
        content = each_text.text
        words = content.lower().split()

        for each_word in words:
            my_wordlist.append(each_word)

    clean_wordlist(my_wordlist)

# ฟังก์ชันลบสัญลักษณ์ที่ไม่ต้องการ
def clean_wordlist(wordlist):
    clean_list = []
    for word in wordlist:
        symbols = '!@#$%^&*()_-+={[}]|\\;:"<>?/., '
        for i in range(len(symbols)):
            word = word.replace(symbols[i], '')
        if len(word) > 0:
            clean_list.append(word)
    create_dictionary(clean_list)

def create_dictionary(clean_list):
    word_count = {}
    for word in clean_list:
        if word in word_count:
            word_count[word] += 1
        else:
            word_count[word] = 1

    c = Counter(word_count)
    # คืนค่าองค์ประกอบที่พบบ่อยที่สุด 10 อันดับแรก
    top = c.most_common(10)
    print(top)

# Driver code
if __name__ == '__main__':
    my_start("https://www.tutorialspoint.com/python3/python_overview.htm/")
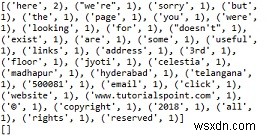
ผลลัพธ์
ข้อควรปรับปรุง: โค้ดนี้เฉพาะเจาะจง class 'entry-content' ของ Tutorialspoint สำหรับเว็บไซต์อื่นต้องปรับ selector ให้เหมาะสม
