

เผยแพร่เมื่อวันที่ 30 เมษายน 2569 เวลา 15:30 น. EDT
Afam มีประสบการณ์ tech publishing ตั้งแต่ 2018 ทำงานที่ Make Tech Easier ตลอดปีสร้าง reputation สำหรับ high-quality guides, reviews, tips, และ explainer articles ครอบคลุม Windows, Linux, และ open source tools งาน featured บน top websites รวม Technical Ustad, Windows Report, Guiding Tech, Alphr, และ Next of Windows
มีปริญญาตรี Computer Science และเป็น strong advocate สำหรับ data privacy และ security มี tips, videos, tutorials บน Fuzo Tech YouTube channel
ตอนไม่ได้งาน ชอบใช้เวลากับครอบครัว ปั่นจักรยาน หรือดูแลสวน
ผมไม่เคยคิดว่าจะ challenging มากขนาดนี้ที่จะรัน local LLM บน Windows แม้จะดู fine ผมก็ realize ภายหลังว่า instance รัน entirely on CPU การตั้งค่า drivers, environment variables และสุดท้าย setup WSL2 หลัง pull Ollama model รู้สึกเหมือน separate project และหลังนั้น ผมพบว่ามัน exhausting มากที่จะ maintain the stack
ผม surprised อย่างยินดีตอนลองบน Linux กระบวนการ direct, ง่ายกว่า และจริงๆ ผมไม่คาดหวังว่าจะมีอะไร break รู้สึกคลตอนผมทำให้ Linux terminal กลายเป็น local AI assistant
Setup ที่ควรใช้ 10 นาที
ทำไม Ollama บน Windows ดึงคุณกลับไปเรื่อยๆ
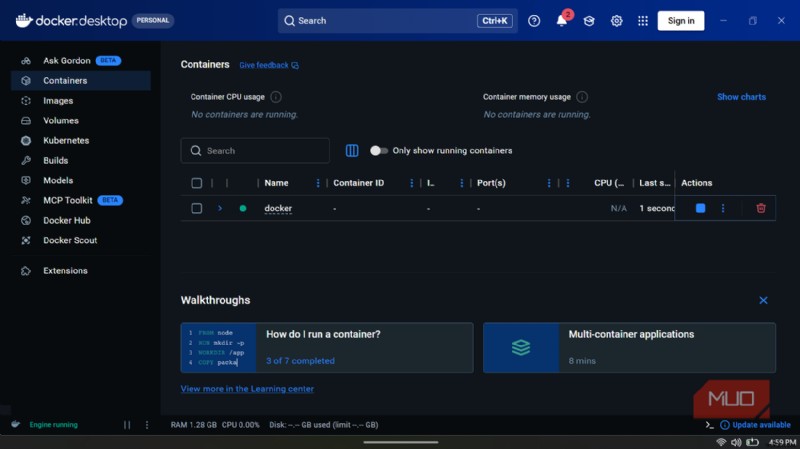
Setup process สำหรับ Ollama บน Windows อาจดู straightforward แต่ในความเป็นจริง ไปไกลกว่า download และ run installer ใน first run คุณอาจ convinced ว่าทุกอย่าง perfect เพราะได้ text และ responses แต่ check ด้วย command: ollama ps เปิดเผย idle GPU เพราะมันรันบน CPU และเพียง 3-5 tokens ต่อวินาที ช้ากว่าที่ควรจะเป็นมาก
Ollama's default silent fallback เป็นเรื่อง common และยาก spot เพราะไม่ emit error พฤติกรรมนี้ possible บน OS อื่นถ้า VRAM น้อยเกินไปสำหรับ model แต่บน Windows factors อื่นๆ หลายอย่าง เช่น driver/installer race conditions, environment variable propagation, และ competing resource usage สามารถ trigger ได้
แม้ไม่มีอะไรดู out of place มันยัง fail ได้ ในกรณีนั้นคุณอาจพึ่ง WSL2 ผมลอง Open WebUI via Docker ซึ่งทำให้ Ollama รู้สึกเหมือน local ChatGPT แม้จะเป็น browser-based service แต่ Docker runs most reliably บน Windows จาก WSL2 นี่คือ Linux environment รันใน Windows และคุณต้อง configure carefully เพื่อหลีกเลี่ยง complications
แน่นอนคุณจะได้ทำถูกต้องสุดท้าย little problem คือ process นี้ never feels like it's really finished เป็น cycle ของ fix one thing, then another, then yet another คุณ never predict ว่าจะใช้เวลานานแค่ไหนได้ working setup อาจ 5 นาที หรือ 5 ชั่วโมง
 บทความเกี่ยวข้อง
5 Linux terminal commands ที่ fix ส่วนใหญ่ของ system problems
Essential Linux troubleshooting commands every user should know.
Linux install จริงๆ เป็นอย่างไร
One command, GPU active, และไม่เหลืออะไรต้อง configure
การติดตั้ง local LLM บน Linux ในการเปรียบเทียบ uneventful (ไม่มีอะไรน่าสนใจ/ราบรื่น) ผมไปจาก one install command สู่ model download, GPU detected และแค่นั้น ตอน generate first response ผมรออยู่อย่างไรก็ต่อกรณีมีอะไร fix ไม่มี
นี่ไม่ใช่คำถามว่า OS ไหน better เพียงแค่ installation script สำหรับ Ollama เขียนสำหรับ Linux ก่อน และทำงาน almost flawlessly ตั้งแต่ install binaries และ register Ollama as background service ที่ start with system ไปจน auto-detect GPU hardware ไม่มีอะไรต้อง bridging layer หรือ environment translation ตราบใดที่ drivers ทั้งหมดในที่ก่อน installation กระบวนการทั้งหมดดูแลตัวเอง
ถ้า GPU detection fail เพราะคุณ install ก่อน drivers confirmed แค่ reinstall Ollama ก็ fix ได้
จากประสบการณ์ นี่คือการเปรียบเทียบ process ในทั้งสอง OS:
Step
Windows
Linux
Install Ollama
.exe installer (GPU use ต้อง verify แยก)
One command (GPU detected automatically)
GPU actually used on first run
บ่อยครั้ง fallback to CPU silently
Used immediately ถ้า drivers ในที่
Open WebUI setup
ต้อง WSL2 installed และ Docker configured ภายใน
Single Docker command
AMD GPU acceleration
Experimental (ROCm v6.1+, frequent CPU fallback reported)
Full support via ROCm v7
Ollama runs at startup
ต้อง manual configuration
Automatic via systemd
Windows supported — Linux คือที่ที่เขียนมัน
เมื่ออยู่ใน ecosystem พอนึง คุณค้นพบว่า Ollama, Open WebUI, และ Docker ไม่ได้ built for Windows และ Python integration รอบๆ พวกมันก็ไม่ได้ Windows support ถูกวางบน top ของพวกมัน และมันทำ significant difference
Best example คือ Open WebUI ซึ่งเป็น single Docker command บน Linux คำสั่งนี้จะ instantly start container ที่ connect ไป local Ollama instance ขณะคุณเปิด browser บน Windows คุณ configure all these elements มันทำงาน แตบ่อยกว่าไม่ได้ใน first attempt ซึ่งนำไปสู่ long debugging process
ปัญหาเหล่านี้ซับซ้อนกว่าสำหรับ AMD GPU users มี full Linux support สำหรับ ROCm version 7 AMD's compute platform สำหรับ GPU inference บน Windows official support หยุดที่ version 6.1+ และยัง experimental ดังนั้น Windows users หลายคนที่มี AMD GPUs ยังคงรัน Ollama บน CPU ไม่ว่า hardware capabilities จะเป็นไร underlying GPU stack เพียงไม่ available
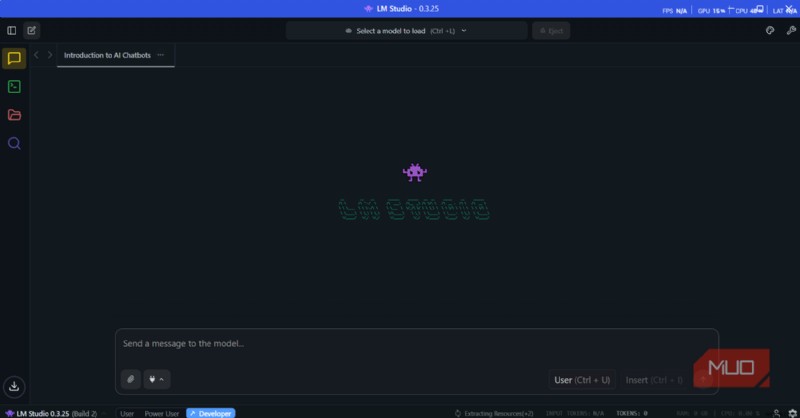
Consider using LM Studio as separate tool จาก Ollama มัน GUI-first รัน clean บน Windows และ Linux และให้คุณรัน models โดยไม่ต้อง terminal แต่ทำงานได้ก็ต่อเมื่อคุณอยาก chat กับ local LLM โดยไม่ทำมากกว่านั้น
เวลาที่คุณประหยัด ไม่ได้แค่ upfront
แม้ผมพบ initial install very fluid ผม appreciate ว่า local LLMs ทำงานบน Linux ยังไงมากขึ้นกับแต่ละ subsequent use ของ setup เหตุผลคือไม่ใช่ one-time install ที่คุณใช้ตลอดไป คุณลอง newer models ตามที่พวกมัน available คุณ constantly trying smaller quantized versions เมื่อ model ช้าเกินไป
ทั้งหมดนี้ require system-level changes initial complications บน Windows สามารถ recur ได้เมื่อคุณทำ changes และจะ only make your experience กับ local LLMs very unpleasant
ถ้าคุณมองหาลอง Linux เพื่อ local LLM ผมแนะนำ Linux Mint มัน probably the best distro สำหรับใครมาจาก Windows ecosystem
 OS Linux
Minimum CPU Specs 64-bit Single-core
Minimum RAM Specs 1.5 GB
Linux Mint คือระบบปฏิบัติการยอดนิยม ฟรี และ open-source สำหรับเดสก์ทอปและแล็ปทอป ใช้งานง่าย มั่นคง และพร้อมทำงาน out of the box
