

ในบทช่วยสอนนี้ คุณจะได้เรียนรู้วิธีใช้ Mechanize ในการคลิกลิงก์ กรอกฟอร์ม และอัปโหลดไฟล์ คุณยังจะได้เรียนรู้วิธีการสไลด์ออบเจ็กต์หน้าเว็บของ Mechanize รวมถึงการทำให้การค้นหา Google เป็นอัตโนมัติและบันทึกผลลัพธ์
หัวข้อที่ครอบคลุม
- หน้าเว็บเดียว vs. การแบ่งหน้า (Pagination)
- Mechanize
- Agent (ตัวแทน)
- Page (หน้าเว็บ)
- เมธอดของ Nokogiri
- ลิงก์ (Links)
- คลิก (Click)
- ฟอร์ม (Forms)
หน้าเว็บเดียว vs. การแบ่งหน้า
จนถึงตอนนี้ เราใช้เวลาค่อนข้างมากในการทำความเข้าใจวิธีสครัปข้อมูลจากหน้าเว็บเพียงหน้าเดียวโดยใช้ Nokogiri ซึ่งเป็นพื้นฐานที่ดีสำหรับการก้าวไปสู่ขั้นตอนถัดไป: การดึงข้อมูลจากหลายหน้าเว็บ
ปัญหาที่เราพยายามแก้คือการดึงเนื้อหาจากมากกว่า 140 ตอน—ซึ่งมากกว่าที่จะรองรับในหน้าเว็บเดียวได้ เราจึงต้องทำงานกับการแบ่งหน้า (pagination) และต้องหาวิธีติดตามเนื้อหาลงไปในหลุมกระต่าย
นี่คือจุดที่ Nokogiri หยุดทำงาน และอีก Ruby Gem ที่มีประโยชน์ชื่อ Mechanize เข้ามามีบทบาท
Mechanize คืออะไร?
Mechanize เป็นเครื่องมืออันทรงพลังอีกตัวหนึ่งที่มีฟีเจอร์มากมาย Gem นี้ช่วยให้คุณทำให้การโต้ตอบกับเว็บไซต์ที่ต้องการดึงข้อมูลเป็นอัตโนมัติ ในมุมมองหนึ่ง มันคล้ายกับฟังก์ชันบางอย่างที่คุณอาจรู้จักจากการทดสอบด้วย Capybara
อย่าเข้าใจผิด การเล่นกับ Nokogiri บนหน้าเว็บเดียวนั้นเก่งแล้ว แต่สำหรับงานดึงข้อมูลที่ซับซ้อนกว่า เราต้องการ "แรงม้า" มากขึ้น เราสามารถครอลผ่านหน้าเว็บได้ไม่จำกัดจำนวน และโต้ตอบกับองค์ประกอบต่างๆ ได้—เลียนแบบและทำให้พฤติกรรมของมนุษย์เป็นอัตโนมัติ สิ่งนี้ทรงพลังมาก!
Gem นี้ช่วยให้คุณติดตามลิงก์ กรอกฟิลด์ฟอร์ม และส่งข้อมูล—รวมถึงจัดการคุกกี้ด้วย นั่นหมายความว่าคุณยังสามารถเลียนแบบการล็อกอินของผู้ใช้เข้าสู่เซสชันส่วนตัว และดึงข้อมูลจากเว็บไซต์ที่เฉพาะคุณเท่านั้นที่เข้าถึงได้
คุณกรอกข้อมูลล็อกอินด้วยข้อมูลประจำตัว และบอก Mechanize ให้ติดตามตามไป ด้วยความสามารถในการคลิกลิงก์และส่งฟอร์ม มีสิ่งน้อยมากที่คุณไม่สามารถทำได้ด้วยเครื่องมือนี้ มันมีความสัมพันธ์ใกล้ชิดกับ Nokogiri และพึ่งพามันด้วย Aaron Patterson ก็เป็นหนึ่งในผู้เขียนของ Gem นี้อีกครั้ง
การสร้าง Mechanize Agent
ก่อนที่เราจะเริ่ม Mechanize ใดๆ เราต้องสร้าง Mechanize Agent ก่อน
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
agent นี้จะถูกใช้เพื่อดึงหน้าเว็บ คล้ายกับสิ่งที่เราทำกับ Nokogiri
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
podcast_url = "https://betweenscreens.fm/"
page = agent.get(podcast_url)
สิ่งที่เกิดขึ้นคือ Mechanize agent ดึงหน้า podcast และคุกกี้ของมันมา
การดึงเนื้อหาจากหน้าเว็บ
ตอนนี้เรามีหน้าเว็บที่พร้อมสำหรับการดึงข้อมูลแล้ว ก่อนจะทำต่อ ผมแนะนำให้ดูโครงสร้างภายในโดยใช้เมธอด inspect
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
podcast_url = "https://betweenscreens.fm/"
page = agent.get(podcast_url)
puts page.inspect
ผลลัพธ์จะมีรายละเอียดมาก ลองดูด้วยตัวเองว่า Mechanize::Page object ประกอบด้วยอะไรบ้าง ที่นี่คุณจะเห็นอ็อบเจ็กต์ทั้งหมดของหน้านั้น และเป็นอ็อบเจ็กต์ที่สะดวกมากสำหรับการสไลด์ข้อมูลที่ต้องการดึง
ตัวอย่าง Output
#<Mechanize::Page {url #https://betweenscreens.fm/>} {meta_refresh} {title "Between | Screens "} {iframes #<Mechanize::Page::Frame nil "https://w.soundcloud.com/player/?url=https%3A//api.soundcloud.com/tracks/290328784&color=ff0000&auto...> ... } {links #<Mechanize::Page::Link "Logo cube" "/"> #<Mechanize::Page::Link "Randy J. Hunt" "episodes/144/"> #<Mechanize::Page::Link "Older Stuff »" "page/2/"> ... } {forms}>
หากต้องการดู HTML ของหน้าเว็บด้วยตัวเอง สามารถใช้เมธอด body หรือ content
some_scraper.rb
... print page.body ...
ตัวอย่าง Output (HTML)
<!doctype html> <html> <head> <meta charset="utf-8" /> ... <title>Between | Screens </title> ... </head> <body> ... <div class='posts'> <ul> <li> <article class="index-article"> <span class='post-date'>Oct 27 | 2016</span><h2 class='post-title'><a href="episodes/144/">Randy J. Hunt</a></h2> ... </article> </li> ... </ul> </div> <section> <div class='pagination-link'><a href="page/2/">Older Stuff »</a></div> </section> ... </body> </html>
เนื่องจาก podcast นี้มีองค์ประกอบไม่มากนัก นี่คือ Mechanize::Page ที่ได้จาก github.com ซึ่งมีเนื้อหาหลากหลายมากกว่า ควรดูเพื่อให้เข้าใจ感覺โดยรวม
Output github.com
#<Mechanize::Page {url #https://github.com/>} {meta_refresh} {title "How people build software · GitHub"} {iframes} {frames} {links #<Mechanize::Page::Link "Skip to content" "#start-of-content"> #<Mechanize::Page::Link "Sign up" "/join?source=header-home"> #<Mechanize::Page::Link "Sign in" "/login"> ... } {forms #<Mechanize::Form {name nil} {method "GET"} {action "/search"} {fields [hidden:0x3feb90f8297c type: hidden name: utf8 value: ✓] [text:0x3feb90f827d8 type: text name: q value: ]} ... > #<Mechanize::Form {name nil} {method "POST"} {action "/join"} {fields [hidden:0x3feb90f7be38 type: hidden name: utf8 value: ✓] [hidden:0x3feb90f7bbb8 type: hidden name: authenticity_token value: ...] [text:0x3feb90f7b9d8 type: text name: user[login] value: ] [text:0x3feb90f7b7f8 type: text name: user[email] value: ] [field:0x3feb90f7b654 type: password name: user[password] value: ] ... } >}>
กลับไปที่ podcast คุณยังสามารถดู encoding, HTTP response code, URI, หรือ response headers ได้
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
podcast_url = "https://betweenscreens.fm/"
page = agent.get(podcast_url)
puts 'Encodings'
puts page.encodings
puts 'Response Headers'
puts page.response
puts 'HTTP response code'
puts page.code
puts 'URI'
puts page.uri
Output
Encodings EUC-JP utf-8 utf-8
Response Headers {"server"=>"GitHub.com", "date"=>"Sat, 29 Oct 2016 17:56:00 GMT", "content-type"=>"text/html; charset=utf-8", "transfer-encoding"=>"chunked", "last-modified"=>"Fri, 28 Oct 2016 01:48:56 GMT", "access-control-allow-origin"=>"*", "expires"=>"Sat, 29 Oct 2016 18:06:00 GMT", "cache-control"=>"max-age=600", "content-encoding"=>"gzip", "x-github-request-id"=>"501C936D:C723:1631523C:5814E2B0"}
HTTP response code 200
URI https://betweenscreens.fm/
ยังมีรายละเอียดอีกมากมายหากต้องการขุดลึก ผมจะหยุดที่นี่
เมธอดของ Nokogiri
atsearch
Mechanize ใช้ Nokogiri ในการสครัปข้อมูลจากหน้าเว็บ คุณสามารถนำสิ่งที่เรียนรู้เกี่ยวกับ Nokogiri จากบทความแรกมาใช้กับหน้าเว็บของ Mechanize ได้ นั่นคือ ใช้ Mechanize สำหรับนำทางหน้าเว็บ และใช้เมธอด Nokogiri สำหรับการสครัปข้อมูล
เช่น ถ้าต้องการค้นหาออบเจ็กต์เดียว ใช้ at ส่วน search จะคืนค่าออบเจ็กต์ทั้งหมดที่ตรงกับ selector บนหน้านั้น เมธอดเหล่านี้ทำงานได้ทั้งกับ Nokogiri document objects และ Mechanize page objects
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
podcast_url = "https://betweenscreens.fm/"
page = agent.get(podcast_url)
first_title = page.at('h2.post-title')
all_titles = page.search('h2.post-title')
all_titles.each do |title|
  puts title
end
puts " * " * 33
puts first_title
Output
<h2 class="post-title"><a href="episodes/144/">Randy J. Hunt</a></h2>
<h2 class="post-title"><a href="episodes/143/">Jason Long</a></h2>
<h2 class="post-title"><a href="episodes/142/">David Heinemeier Hansson</a></h2>
<h2 class="post-title"><a href="episodes/141/">Zach Holman</a></h2>
<h2 class="post-title"><a href="episodes/140/">Joel Glovier</a></h2>
<h2 class="post-title"><a href="episodes/139/">João Ferreira</a></h2>
<h2 class="post-title"><a href="episodes/138/">Corwin Harrell</a></h2>
* * * * * * * * * * * * * * * * * * * * * * * * * * * * * * * * *
<h2 class="post-title"><a href="episodes/144/">Randy J. Hunt</a></h2>
ลิงก์ (Links)
linkslink_withlinks_with
เราสามารถนำทางเว็บไซต์ทั้งหมดตามใจชอบ ส่วนที่สำคัญที่สุดของ Mechanize คือความสามารถในการเล่นกับลิงก์—มิฉะนั้นก็แค่ใช้ Nokogiri อย่างเดียวพอ ลองดูว่าจะได้อะไรเมื่อขอลิงก์จากหน้าเว็บ
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
podcast_url = "https://betweenscreens.fm/"
page = agent.get(podcast_url)
puts "#{page.links}"
Output
[#<Mechanize::Page::Link "Logo cube" "/"> , #<Mechanize::Page::Link "about" "pages/about/"> , #<Mechanize::Page::Link "design" "design/"> , #<Mechanize::Page::Link "code" "code/"> , #<Mechanize::Page::Link "Randy J. Hunt" "episodes/144/"> , #<Mechanize::Page::Link "Jason Long" "episodes/143/"> , #<Mechanize::Page::Link "David Heinemeier Hansson" "episodes/142/"> , #<Mechanize::Page::Link "Zach Holman" "episodes/141/"> , #<Mechanize::Page::Link "Joel Glovier" "episodes/140/"> , #<Mechanize::Page::Link "João Ferreira" "episodes/139/"> , #<Mechanize::Page::Link "Corwin Harrell" "episodes/138/"> , #<Mechanize::Page::Link "Older Stuff »" "page/2/"> , #<Mechanize::Page::Link "Exercise" "/tags/exercise/"> , #<Mechanize::Page::Link "Company benefits" "/tags/company-benefits/"> , #<Mechanize::Page::Link "Tmux" "/tags/tmux/"> , #<Mechanize::Page::Link "FileTask" "/tags/filetask/"> , #<Mechanize::Page::Link "Decision making" "/tags/decision-making/"> , #<Mechanize::Page::Link "Favorite feature" "/tags/favorite-feature/"> , #<Mechanize::Page::Link "Working out" "/tags/working-out/"> , #<Mechanize::Page::Link "Scott Savarie" "/tags/scott-savarie/"> , #<Mechanize::Page::Link "Titles" "/tags/titles/"> , #<Mechanize::Page::Link "Erik Spiekermann" "/tags/erik-spiekermann/"> , #<Mechanize::Page::Link "Newbie mistakes" "/tags/newbie-mistakes/"> , #<Mechanize::Page::Link "Playbook" "/tags/playbook/"> , #<Mechanize::Page::Link "Delegation" "/tags/delegation/"> , #<Mechanize::Page::Link "Heat maps" "/tags/heat-maps/"> , #<Mechanize::Page::Link "Europe" "/tags/europe/"> , #<Mechanize::Page::Link "Sizing type" "/tags/sizing-type/"> , #<Mechanize::Page::Link "Focus" "/tags/focus/"> , #<Mechanize::Page::Link "Virtual assistants" "/tags/virtual-assistants/"> , #<Mechanize::Page::Link "Writing" "/tags/writing/"> , #<Mechanize::Page::Link "Hacking" "/tags/hacking/"> , #<Mechanize::Page::Link "Joel Glovier" "/tags/joel-glovier/"> , #<Mechanize::Page::Link "Corwin Harrell" "/tags/corwin-harrell/"> , #<Mechanize::Page::Link "Mario C. Delgado" "/tags/mario-c-delgado/"> , #<Mechanize::Page::Link "Tom Dale" "/tags/tom-dale/"> , #<Mechanize::Page::Link "Obie Fernandez" "/tags/obie-fernandez/"> , #<Mechanize::Page::Link "Chad Pytel" "/tags/chad-pytel/"> , #<Mechanize::Page::Link "Zach Holman" "/tags/zach-holman/"> , #<Mechanize::Page::Link "Max Luster" "/tags/max-luster/"> , #<Mechanize::Page::Link "Kyle Fiedler" "/tags/kyle-fiedler/"> , #<Mechanize::Page::Link "Roberto Machado" "/tags/roberto-machado/"> ]
Mechanize ส่งคืนอาร์เรย์ของลิงก์จากหน้าแรกเท่านั้น เรียงจากบนลงล่าง ตามลำดับในหน้าเว็บ
ภาพหน้าจอตัวอย่าง
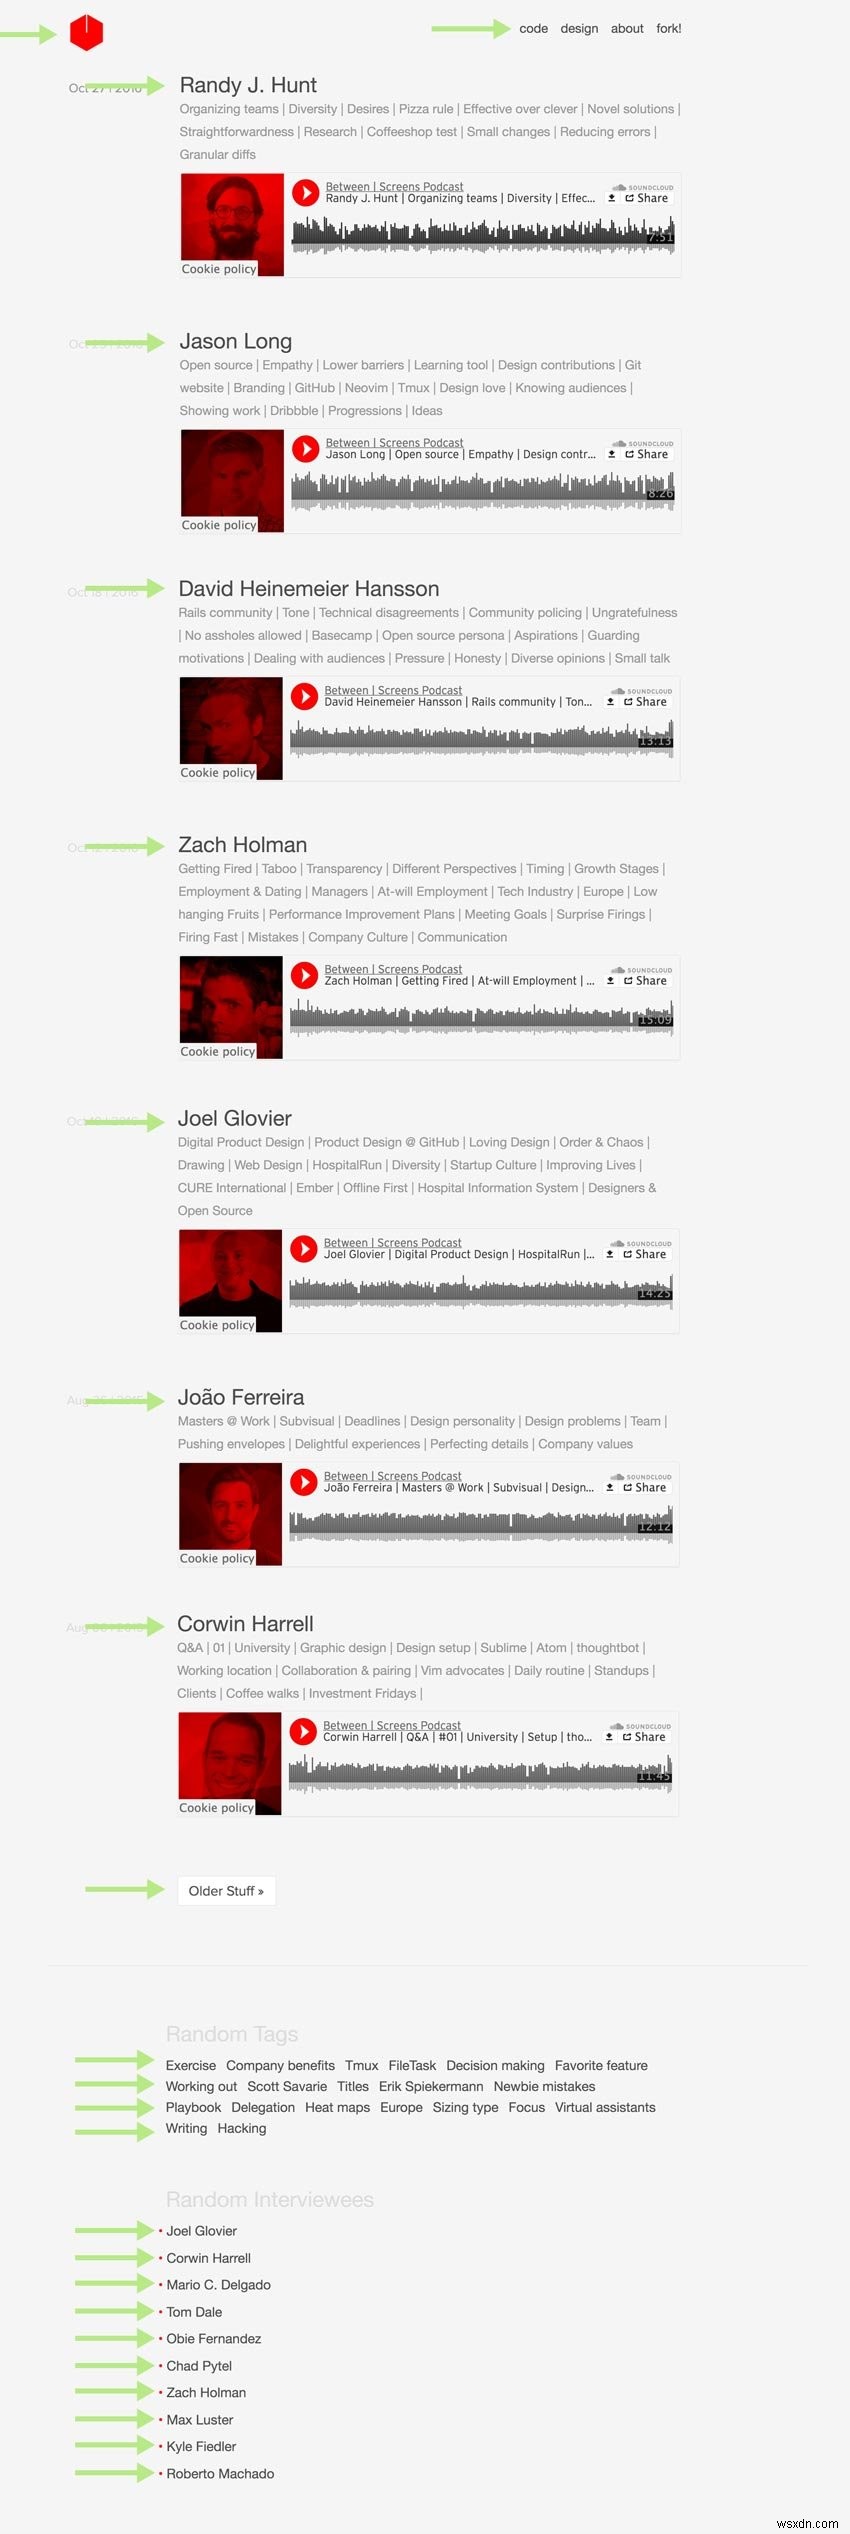
เราสามารถดึงเฉพาะข้อความของลิงก์ได้เช่นกัน
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
podcast_url = "https://betweenscreens.fm/"
page = agent.get(podcast_url)
page.links.each do |link|
  puts link.text
end
Output
Logo cube fork! about design code Randy J. Hunt Jason Long David Heinemeier Hansson Zach Holman Joel Glovier João Ferreira Corwin Harrell Older Stuff » Exercise Company benefits Tmux FileTask Decision making Favorite feature Working out Scott Savarie Titles Erik Spiekermann Newbie mistakes Playbook Delegation Heat maps Europe Sizing type Focus Virtual assistants Writing Hacking Joel Glovier Corwin Harrell Mario C. Delgado Tom Dale Obie Fernandez Chad Pytel Zach Holman Max Luster Kyle Fiedler Roberto Machado
การได้ลิงก์ทั้งหมดแบบนี้อาจมีประโยชน์หรืออาจรุ่งเรืองเกินไป Mechanize มีเครื่องมือช่วยกรองให้แม่นยำขึ้น
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
podcast_url = "https://betweenscreens.fm/"
page = agent.get(podcast_url)
focus_link = agent.page.links.find { |link| link.text == 'Focus' }
puts focus_link
Output
Focus
เราสามารถระบุลิงก์ที่ตรงตามเกณฑ์เฉพาะ เช่น ข้อความ (text) ด้วย API ที่สะดวกกว่าคือ links_with หรือ link_with หากมีลิงก์ "Focus" หลายอัน สามารถระบุลำดับด้วย bracket []
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
podcast_url = "https://betweenscreens.fm/"
page = agent.get(podcast_url)
focus_link = agent.page.links_with(:text => 'Focus')[2]
puts focus_link
หากต้องการค้นหาจาก href แทนข้อความ ให้ใช้ href แทน text
some_scraper.rb
page = agent.page.link_with(href: '/episodes/95/')
page = agent.page.links_with(href: '/episodes/95/')
หากต้องการลิงก์แรกที่ตรงตามข้อความ ใช้ syntax นี้
some_scraper.rb
focus_links = agent.page.link_with(:text => 'Focus')
ลอง click ลิงก์ Focus ดูสิว่ามีอะไรอยู่ด้านหลัง!
คลิก (Click)
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
podcast_url = "https://betweenscreens.fm/"
page = agent.get(podcast_url)
focus_links = agent.page.links.find { |link| link.text == 'Focus' }.click.links
puts focus_links
Mechanize จะคลิกลิงก์ให้ และติดตามไปยังหน้าใหม่ แล้วคืนค่าลิงก์ทั้งหมดที่พบบนหน้าใหม่นั้น
เช่น ถ้ามีลิงก์สองอันของ interviewee คนเดียวกัน—อันนำไปหน้าแท็ก อันนำไปหน้าตอนล่าสุด—และต้องการลิงก์จากทั้งสองหน้า:
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
podcast_url = "https://betweenscreens.fm/"
page = agent.get(podcast_url)
links = agent.page.links_with(text: "Some interviewee")
links.each do |link|
  puts link.click.links
end
จะได้ลิงก์จากทั้งสองหน้า นี่คือตัวอย่าง combinations ต่างๆ เพื่อเริ่มต้น:
some_scraper.rb
agent.page.links.find { |l| l.text == 'Focus' }
agent.page.links.find { |l| l.text == 'Focus' }.click
agent.page.link_with(text: 'Focus')
agent.page.links_with(text: 'Focus')[0]
agent.page.links_with(text: 'Focus')[1].click
agent.page.links_with(text: 'Focus')[2].click.links
agent.page.link_with(href: '/some-href')
agent.page.link_with(href: '/some-href').click
agent.page.links_with(href: '/some-href')
agent.page.links_with(href: '/some-href').click
ฟอร์ม (Forms)
submitfield_withcheckbox_withradiobuttons_withfile_uploads
มาดูฟอร์มกัน!
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
google_url = "https://google.com/"
page = agent.get(google_url)
forms = page.forms
puts forms.inspect
Output
[#<Mechanize::Form {name "f"} {method "GET"} {action "/search"} {fields [hidden:0x3fea91d2eb08 type: hidden name: ie value: ISO-8859-1] [hidden:0x3fea91d2e964 type: hidden name: hl value: es] [hidden:0x3fea91d2e7e8 type: hidden name: source value: hp] [hidden:0x3fea91d2e5f4 type: hidden name: biw value: ] [hidden:0x3fea91d2e428 type: hidden name: bih value: ] [text:0x3fea91d2e248 type: name: q value: ] [hidden:0x3fea91d2bcb4 type: hidden name: gbv value: 1]} {radiobuttons} {checkboxes} {file_uploads} {buttons [submit:0x3fea91d2e0f4 type: submit name: btnG value: Buscar con Google] [submit:0x3fea91d2be80 type: submit name: btnI value: Voy a tener suerte]}> ]
เมธอด forms คืนค่าเป็นอาร์เรย์ แม้จะมีฟอร์มเดียว กรณีนี้ฟอร์มมีชื่อ "f" เราสามารถใช้ form (เอกพจน์) เพื่อระบุฟอร์มเฉพาะนั้น
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
google_url = "https://google.com/"
page = agent.get(google_url)
search_form = page.form('f')
puts search_form.inspect
ใช้ form('f') จะได้ฟอร์มเดียว ไม่ใช่อาร์เรย์
Output
#<Mechanize::Form {name "f"} {method "GET"} {action "/search"} {fields [hidden:0x3ffe9ce85ba4 type: hidden name: ie value: ISO-8859-1] [hidden:0x3ffe9ce859d8 type: hidden name: hl value: es] [hidden:0x3ffe9ce857bc type: hidden name: source value: hp] [hidden:0x3ffe9ce85618 type: hidden name: biw value: ] [hidden:0x3ffe9ce853e8 type: hidden name: bih value: ] [text:0x3ffe9ce851cc type: name: q value: ] [hidden:0x3ffe9ce84bdc type: hidden name: gbv value: 1]} {radiobuttons} {checkboxes} {file_uploads} {buttons [submit:0x3ffe9ce85078 type: submit name: btnG value: Buscar con Google] [submit:0x3ffe9ce84e48 type: submit name: btnI value: Voy a tener suerte]}>
เห็นฟิลด์ข้อความชื่อ q เราสามารถตั้งค่าได้เหมือน attribute ของ Ruby
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
google_url = "https://google.com/"
page = agent.get(google_url)
search_form = page.form('f')
search_form.q = 'New Google Search'
puts search_form.inspect
Output
#<Mechanize::Form {name "f"} {method "GET"} {action "/search"} {fields [hidden:0x3fcb85b6a784 type: hidden name: ie value: ISO-8859-1] [hidden:0x3fcb85b6a57c type: hidden name: hl value: es] [hidden:0x3fcb85b6a3b0 type: hidden name: source value: hp] [hidden:0x3fcb85b6a16c type: hidden name: biw value: ] [hidden:0x3fcb85b67f20 type: hidden name: bih value: ] [text:0x3fcb85b67d18 type: name: q value: New Google Search] [hidden:0x3fcb85b67728 type: hidden name: gbv value: 1]} {radiobuttons} {checkboxes} {file_uploads} {buttons [submit:0x3fcb85b67b9c type: submit name: btnG value: Buscar con Google] [submit:0x3fcb85b67994 type: submit name: btnI value: Voy a tener suerte]}>
ค่าของฟิลด์ข้อความเปลี่ยนเป็น New Google Search แล้ว ต่อไปแค่ submit ฟอร์ม และเก็บผลลัพธ์จากหน้าที่ Google คืนมา
some_scraper.rb
require 'mechanize'
agent = Mechanize.new
google_url = "https://google.com/"
page = agent.get(google_url)
search_form = page.form('f')
search_form.q = 'GitHub TouchFart'
page = agent.submit(search_form)
pp page.search('h3.r').map(&:text)
ที่นี่ใช้ CSS selector h3.r สำหรับ header ผลค้นหา map text และ pretty print ผลลัพธ์ ไมยากเลยใช่ไหม?
Output
["GitHub - hungtruong/TouchFart: A fart app for the new Macbook ...", "TouchFart/TouchFart at master · hungtruong/TouchFart · GitHub", "Commits · hungtruong/TouchFart · GitHub", "Projects · hungtruong/TouchFart · GitHub", "Pull Requests · hungtruong/TouchFart · GitHub", "Issues · hungtruong/TouchFart · GitHub", "TouchFart/license.txt at master · hungtruong/TouchFart · GitHub", "Add autoplay attribute to <audio> tag and touchfart (er ... - GitHub", "Find file - File Finder · GitHub", "Fart app for the new Macbook Pro's Touch... #3860 on topic touchfart ..."]
Mechanize มี input fields หลากหลาย รวมถึงอัปโหลดไฟล์!
field_withcheckbox_withradiobuttons_withfile_uploads
ระบุ radio buttons และ checkboxes โดย name แล้ว check ได้เลย
some_scraper.rb
form.radiobuttons_with(:name => 'gender')[3].check
form.checkbox_with(:name => 'coder').check
สำหรับ dropdown (option tags) ระบุ name และเลือก option ตามลำดับ
some_scraper.rb
form.field_with(:name => 'countries').options[22].select
อัปโหลดไฟล์ทำงานคล้ายการกรอกข้อความ ระบุฟิลด์อัปโหลด แล้วกำหนด path ไฟล์
some_scraper.rb
form.file_uploads.first.file_name = "some-path/some-image.jpg"
ข้อคิดสุดท้าย
เห็นไหม ไม่มีเวทมนตร์อะไรเลย! ตอนนี้คุณพร้อมลองเล่นเองแล้ว ยังมีรายละเอียดของ Nokogiri และ Mechanize ให้เรียนรู้อีก แต่แทนที่จะลงลึกในรายละเอียดที่ไม่จำเป็น ลองเล่นจริงๆ และอ่าน documentation เมื่อเจอปัญหาที่เกินขอบเขตบทความระดับเริ่มต้น
หวังว่าคุณจะเห็นว่า Gem นี้เรียบง่ายแต่อันทรงพลัง ดังที่รู้กันดีจากวัฒนธรรมยุคใหม่ "พลังมากับความรับผิดชอบ" ใช้ในกรอบกฎหมาย และเมื่อไม่มี API ให้ใช้ คุณอาจไม่ได้ใช้บ่อย แต่เมื่อต้องสครัปจริง มันช่วยได้มาก!
ตามสัญญา บทความหน้าเราจะทำตัวอย่างจริง: สครัปข้อมูลจากเว็บ podcast เก่า (Sinatra) และย้ายไป Middleman ใหม่ที่ใช้ไฟล์ .markdown ต่อตอน จะดึงวันที่, หมายเลขตอน, ชื่อผู้สัมภาษณ์, หัวข้อ, หัวข้อย่อย ฯลฯ พบกันใหม่!
