

ในงานนี้เราทำงานกับไฟล์ ไฟล์มีอยู่ทุกที่ในจักรวาล ระบบคอมพิวเตอร์ไฟล์เป็นส่วนสำคัญ ระบบปฏิบัติการประกอบด้วยไฟล์จำนวนมาก
Python มีไฟล์ 2 ประเภท: Text Files และ Binary Files
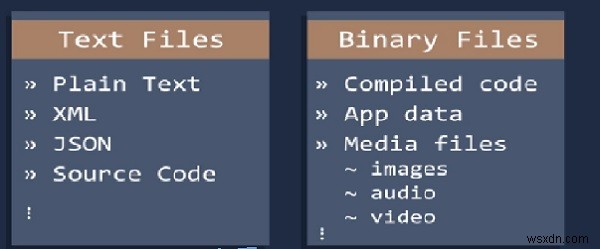
ที่นี่เราจะเน้นเฉพาะ Text Files และฟังก์ชันสำคัญต่างๆ:
- จำนวนคำ (Number of words)
- จำนวนตัวอักษร (Number of characters)
- ความยาวคำเฉลี่ย (Average word length)
- จำนวน Stop words
- จำนวนอักขระพิเศษ (Special characters)
- จำนวนตัวเลข (Numeric)
- จำนวนคำพิมพ์ใหญ่ (Uppercase words)
เรามีไฟล์ทดสอบ "css3.txt" สำหรับทดสอบ
1. นับจำนวนคำ
ใช้ฟังก์ชัน split() แยกคำ แล้วนับจำนวน
filename = "C:/Users/TP/Desktop/css3.txt"
try:
    with open(filename) as file_object:
        contents = file_object.read()
except FileNotFoundError:
    message = "Sorry, " + filename + " not found."
    print(message)
else:
    words = contents.split()
    number_words = len(words)
    print("Total words of", filename, "is", str(number_words))
ผลลัพธ์
Total words of C:/Users/TP/Desktop/css3.txt is 35742. นับจำนวนตัวอักษร
filename = "C:/Users/TP/Desktop/css3.txt"
try:
    with open(filename) as file_object:
        contents = file_object.read()
except FileNotFoundError:
    print("Sorry, " + filename + " not found.")
else:
    wordslist = contents.split()
    characters = sum(len(word) for word in wordslist)
    print("TOTAL CHARACTERS IN A TEXT FILE =", characters)
ผลลัพธ์
TOTAL CHARACTERS IN A TEXT FILE = 177833. ความยาวคำเฉลี่ย
filename = "C:/Users/TP/Desktop/css3.txt"
try:
    with open(filename) as file_object:
        contents = file_object.read()
except FileNotFoundError:
    print("Sorry, " + filename + " not found.")
else:
    wordslist = contents.split()
    words = len(wordslist)
    average = sum(len(word) for word in wordslist) / words
    print("Average =", average)
ผลลัพธ์
Average = 4.974. นับ Stop Words (ใช้ NLP)
from nltk.corpus import stopwords
from nltk.tokenize import word_tokenize

my_example_sent = "This is a sample sentence"
mystop_words = set(stopwords.words('english'))
my_word_tokens = word_tokenize(my_example_sent)

my_filtered_sentence = [w for w in my_word_tokens if w not in mystop_words]

print("Original:", my_word_tokens)
print("Filtered:", my_filtered_sentence)
5. นับอักขระพิเศษ (เช่น #, @)
import collections as ct

filename = "C:/Users/TP/Desktop/css3.txt"
try:
    with open(filename) as file_object:
        contents = file_object.read()
except FileNotFoundError:
    print("Sorry, " + filename + " not found.")
else:
    words = contents.split()
    special_chars = "#"
    count = sum(v for k, v in ct.Counter(words).items() if k in special_chars)
    print("Total Special Characters:", count)
ผลลัพธ์
Total Special Characters 06. นับตัวเลข
filename = "C:/Users/TP/Desktop/css3.txt"
try:
    with open(filename) as file_object:
        contents = file_object.read()
except FileNotFoundError:
    print("Sorry, " + filename + " not found.")
else:
    numeric_count = sum(map(str.isdigit, contents.split()))
    print("TOTAL NUMERIC IN A TEXT FILE =", numeric_count)
ผลลัพธ์
TOTAL NUMERIC IN A TEXT FILE = 27. นับคำพิมพ์ใหญ่ทั้งหมด
filename = "C:/Users/TP/Desktop/css3.txt"
try:
    with open(filename) as file_object:
        contents = file_object.read()
except FileNotFoundError:
    print("Sorry, " + filename + " not found.")
else:
    uppercase_count = sum(map(str.isupper, contents.split()))
    print("TOTAL UPPERCASE WORDS IN A TEXT FILE =", uppercase_count)
ผลลัพธ์
TOTAL UPPERCASE WORDS IN A TEXT FILE = 121สรุป: Python มีเครื่องมือครบครันสำหรับการวิเคราะห์ข้อความ ตั้งแต่พื้นฐานไปจนถึง NLP ขั้นสูง
