

เคยสังเกตไหมว่า search boxes แนะนำคำขณะพิมพ์? จริงๆ แล้ว suggestions ส่วนใหญ่ขึ้นตาม alphabetical order และไม่ค่อย helpful
แตถ้ search box ได้ smarter ตามเวลาล่ะ?
เรียนรู้จากสิ่งที่คน click จริง และแสดง popular results ก่อน?
นี่คือสิ่งที่เราจะสร้าง:
เราจะดูว่า Redis Sorted Sets สามารถ power intelligent autocomplete system ที่ learns จาก user behavior และกลายเป็น accurate มากขึ้น (แสดง popular results first) ตามเวลา
The Idea of Smart Autocomplete Systems (ไอเดีย Smart Autocomplete Systems)
Basic search box ใช้ method ที่เรียกว่า prefix matching เพื่อตัดสินใจว่าจะแสดง results ไหนก่อน
ขณะพิมพ์ มันแสดง matches ตาม A-Z order มันไม่สนใจจริงๆ ว่าผู้ใช้ click ผลไหนมากที่สุด
เราจะทำให้มัน smart มากขึ้น Search box ของเราจะ เรียนรู้จากสิ่งที่คนเลือก เมื่อคน click search result เราจะแสดง result นั้น first ตั้งแต่ครั้งต่อไป
นี่หมายความว่า search ของเรา better และ helpful มากขึ้นตามเวลาโดยอัตโนมัติแสดง most popular results ที่ top
Why This Matters for Search Applications (ทำไมมันสำคัญสำหรับ Search Applications)
พิจารณา movie search application: เมื่อ users พิมพ์ "int" พวกเขาอาจเห็น:
- "Interceptor"
- "Interstate 60"
- "Interstellar"
ใน "traditional" system พวกมันจะขึ้น alphabetically อย่างไรก็ตาม ถ้าผู้ใช้ consistently click "Interstellar" เราอยาก promote มันไป top ของ autocomplete suggestions
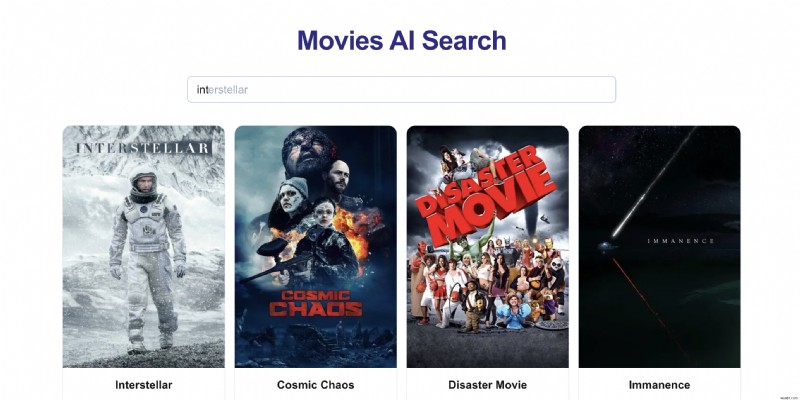
Smart ranking system นี้ทำงานดีมากสำหรับ:
- Streaming services อย่าง Netflix หรือ YouTube แสดงสิ่งที่คนดูมากที่สุด
- Online stores แสดง popular products first ตอน search
- Help centers แสดง most common questions ที่คนถาม
- Any website with search แสดงสิ่งที่ส่วนใหญ่ click first
Understanding Redis Sorted Sets (การเข้าใจ Redis Sorted Sets)
มาเข้าใจว่า Redis Sorted Sets เก่งสำหรับ autocomplete system อย่างไร
Redis Sorted Set เหมือน smart list ที่:
- แต่ละ item unique (เหมือน set)
- แต่ละ item มี score (สำหรับ ordering)
- Items สามารถ sorted by scores ได้เร็ว
สำหรับ autocomplete system เราจะใช้ 2 sorted sets:
- หนึ่งสำหรับ matching text prefixes (เช่น "int" match "interstellar")
- อีกอันสำหรับ track popularity ของแต่ละ suggestion
ทั้ง 2 sets ทำงานร่วมกันเพื่อ suggest most relevant results ขณะ users พิมพ์
The Foundation: Alphabetical Ordering (Foundation: การจัดลำดับ Alphabetical)
Redis Sorted Sets maintain alphabetical ordering เมื่อ all members มี score เหมือนกัน นี่ perfect สำหรับสร้าง search suggestions เพราะมันให้เรา:
- Store all prefixes ของ searchable terms ใน single data structure
- Use
ZRANKหา starting position ของ prefix ใดๆ ใน O(log N) time - Use
ZSCANretrieve all matches เริ่มจาก position นั้นอย่างมีประสิทธิภาพ - Use
ZMSCOREได้ popularity score ของแต่ละ match - Use
ZINCRBYincrement popularity score ของแต่ละ match
มาดูตัวอย่างง่าย ตอนเราเพิ่ม movie "INTERSTELLAR" เข้า search system เราแยกมันแบบนี้:
- Score: 0, Member: "I"
- Score: 0, Member: "IN"
- Score: 0, Member: "INT"
- Score: 0, Member: "INTE"
- Score: 0, Member: "INTER"
- Score: 0, Member: "INTERSTELLAR$Interstellar" (complete entry พร้อม display format)
เห็นไหมเราใช้ $ แยก search version จาก display version? ทางนี้ users search ได้ไม่ว่าจะ uppercase/lowercase แตเรายังแสดง movie title ตรงตามที่ควร
How We Store the Data (เราเก็บข้อมูลอย่างไร)
เราใช้ 2 Redis sorted sets ทำให้ autocomplete ทำงาน:
1. Movie Titles List (รายการชื่อหนัง)
เก็บ sorted set ชื่อ movies คิดว่านี่เหมือน dictionary ช่วยหาหนังเร็ว ตอนใครพิมพ์ "int" เราหาหนังที่ขึ้นต้นตัวอักษรเหล่านั้นได้ทันที
First occurrence ของ "int" จะหาได้โดย ZRANK และจาก position นั้น full movie names ด้วย wild card INT*$* จะถูก fetch
2. Popular Movies List (รายการหนังยอดนิยม)
เก็บ sorted set ชื่อ movie-popularity นี่คือ "trending movies" list ของเรา
ทุกครั้งที่คน click หนังใน search results หนังนั้นได้ popularity มากขึ้นโดย increment score ด้วย ZINCRBY หนังที่ถูก click มากที่สุดขึ้น first ใน future searches
เหมือน Netflix แสดง trending movies - ยิ่งคนดูเยอะ ยิ่งขึ้นสูงใน recommendations
ในกรณีเรา หลังหา exact matches สำหรับ INT*$* เราไปเช็ค scores ที่ movie-popularity เพื่อได้ most popular ones
The Algorithmic Flow (Algorithmic Flow)
graph TD A[User types 'int'] --> B[ZRANK: Find lexicographic position of 'INT'] B --> C[ZSCAN: Retrieve matches starting from position (movies set)] C --> D[Filter: Extract complete terms containing '$'] D --> E[ZMSCORE: Get popularity scores for all matches (movie-popularity set)] E --> F[Rank: Return highest-scored suggestion] G[User selects suggestion] --> H[ZINCRBY: Increment popularity score] H --> I[Future searches: Higher scored items rank first] I --> Aเมื่อ users search และ click suggestions ระบบ learns และ improves ยิ่งคนใช้มาก ยิ่งเก่งแสดง most relevant suggestions first
Let's Build the Autocomplete System (มาสร้าง Autocomplete System)
มาดูว่าเราสร้างระบบนี้ step by step จะเก็บมัน super simple!
Step 1: Adding Movie Titles to Redis
ก่อนอื่น เราต้องเพิ่ม movie titles เข้า Redis เพื่อ search ภายหลัง เริ่มจาก simple list of movies จาก anywhere - อาจ database หรือแค่ text file นี่คือวิธีเพิ่ม:
import { Redis } from "@upstash/redis"; const redis = new Redis({ url: process.env.UPSTASH_REDIS_URL!, token: process.env.UPSTASH_REDIS_TOKEN!, }); // Example: your list of titles const titles = [ "Interceptor", "Interstate 60", "Interstellar", // ... more titles ]; async function populateAutocomplete() { // Insert prefixes และ full titles into 'movies' sorted set for (const title of titles) { let term = title.toUpperCase(); let terms = []; for (let i = 1; i < term.length; i++) { terms.push({ score: 0, member: term.substring(0, i) }); } terms.push({ score: 0, member: term }); terms.push({ score: 0, member: term + "$" + title }); await redis.zadd("movies", ...terms); } // Insert all titles into 'movie-popularity' sorted set สำหรับ popularity tracking await redis.zadd( "movie-popularity", ...titles.map((title) => ({ score: 0, member: title.toUpperCase(), })), ); } populateAutocomplete();มาแยกว่าโค้ดข้างต้นทำอะไร:
-
สำหรับแต่ละ movie title เราเก็บ:
- All possible partial matches (อย่าง "INT", "INTE", "INTER" สำหรับ "Interstellar")
- Complete title เอง
- Formatted version สำหรับ display
-
เราสร้าง separate list track popularity ของแต่ละ movie เริ่มที่ zero views
นี่ให้ทุกอย่างที่ต้องการ show smart suggestions ขณะ users พิมพ์ และ learn จากสิ่งที่พวกเขา click
Step 2: Finding the Best Matches (การหา Best Matches)
ต่อไป เราดูว่า search ผ่าน movie titles หา matches ยังไง matchQuery function ทำ heavy lifting:
export const matchQuery = async (query: string): Promise<string | null> => { const upperQuery = query.toUpperCase(); // Step 1: Find starting position using lexicographic ordering let rank = await redis.zrank("movies", upperQuery); if (rank === null) return null; // Step 2: Efficiently scan for matches from that position const scanResult = await redis.zscan("movies", rank, { match: `${upperQuery}*$*`, count: 1000, }); // Step 3: Extract complete entries และได้ popularity scores const completeTitles = scanResult[1].filter( (el, idx) => idx % 2 === 0 && el.includes("$"), ); const baseNames = completeTitles.map((title) => title.split("$")[0]); const scores = await redis.zmscore("movie-popularity", baseNames); // Step 4: Return highest-scored (most popular) match const maxScore = Math.max(...scores); const bestMatchIndex = scores.indexOf(maxScore); return completeTitles[bestMatchIndex].split("$")[1]; };Learning from User Choices (เรียนรู้จาก User Choices)
ตอนใคร select movie title เราเพิ่ม 1 point ให้ score หนังที่มี points มากขึ้นขึ้นสูงกว่าใน suggestions list มัน simple ขนาดนั้น!
ระบบได้ smart มากขึ้นตามเวลาด้วยการ track สิ่งที่คนจริงๆ เลือก
const onSubmit = async (title: string) => { // Handle submit logic here await redis.zincrby("movie-popularity", 1, title.toUpperCase()); };How Fast Is It? (มันเร็วแค่ไหน?)
มาดูว่าสโลูชันนี้เร็วแค่ไหนโดยแยกเวลาแต่ละ operation:
- ZRANK: O(log N) - Logarithmic lookup time
- ZSCAN: O(log N + M) - M คือจำนวน returned elements
- ZMSCORE: O(N) - N คือจำนวน matched results ไม่ใช่ total dataset size
- ZINCRBY: O(log N) - Atomic increment with logarithmic complexity
เมื่อเราเพิ่ม movie titles มากขึ้น performance คงที่
Conclusion: What We Built Together (สรุป: สิ่งที่เราสร้างร่วมกัน)
คุณเพิ่งเรียนรู้วิธีสร้าง smart search box ที่ better ตามเวลาโดยไม่ต้อง AI!
Autocomplete ของเรา learns จากสิ่งที่คนเลือก และใช้ข้อมูลนั้นแสดง better suggestions
มัน fast, simple และกลายเป็น helpful มากขึ้นยิ่งคนใช้เยอะ
อยากคุย Redis optimization strategies หรือ share implementations ของตัวเอง? เข้าร่วม Discord กับเรา!
